- 流程具有预定义的代码路径,按特定顺序运行。
- 智能体动态定义自身流程和工具使用。
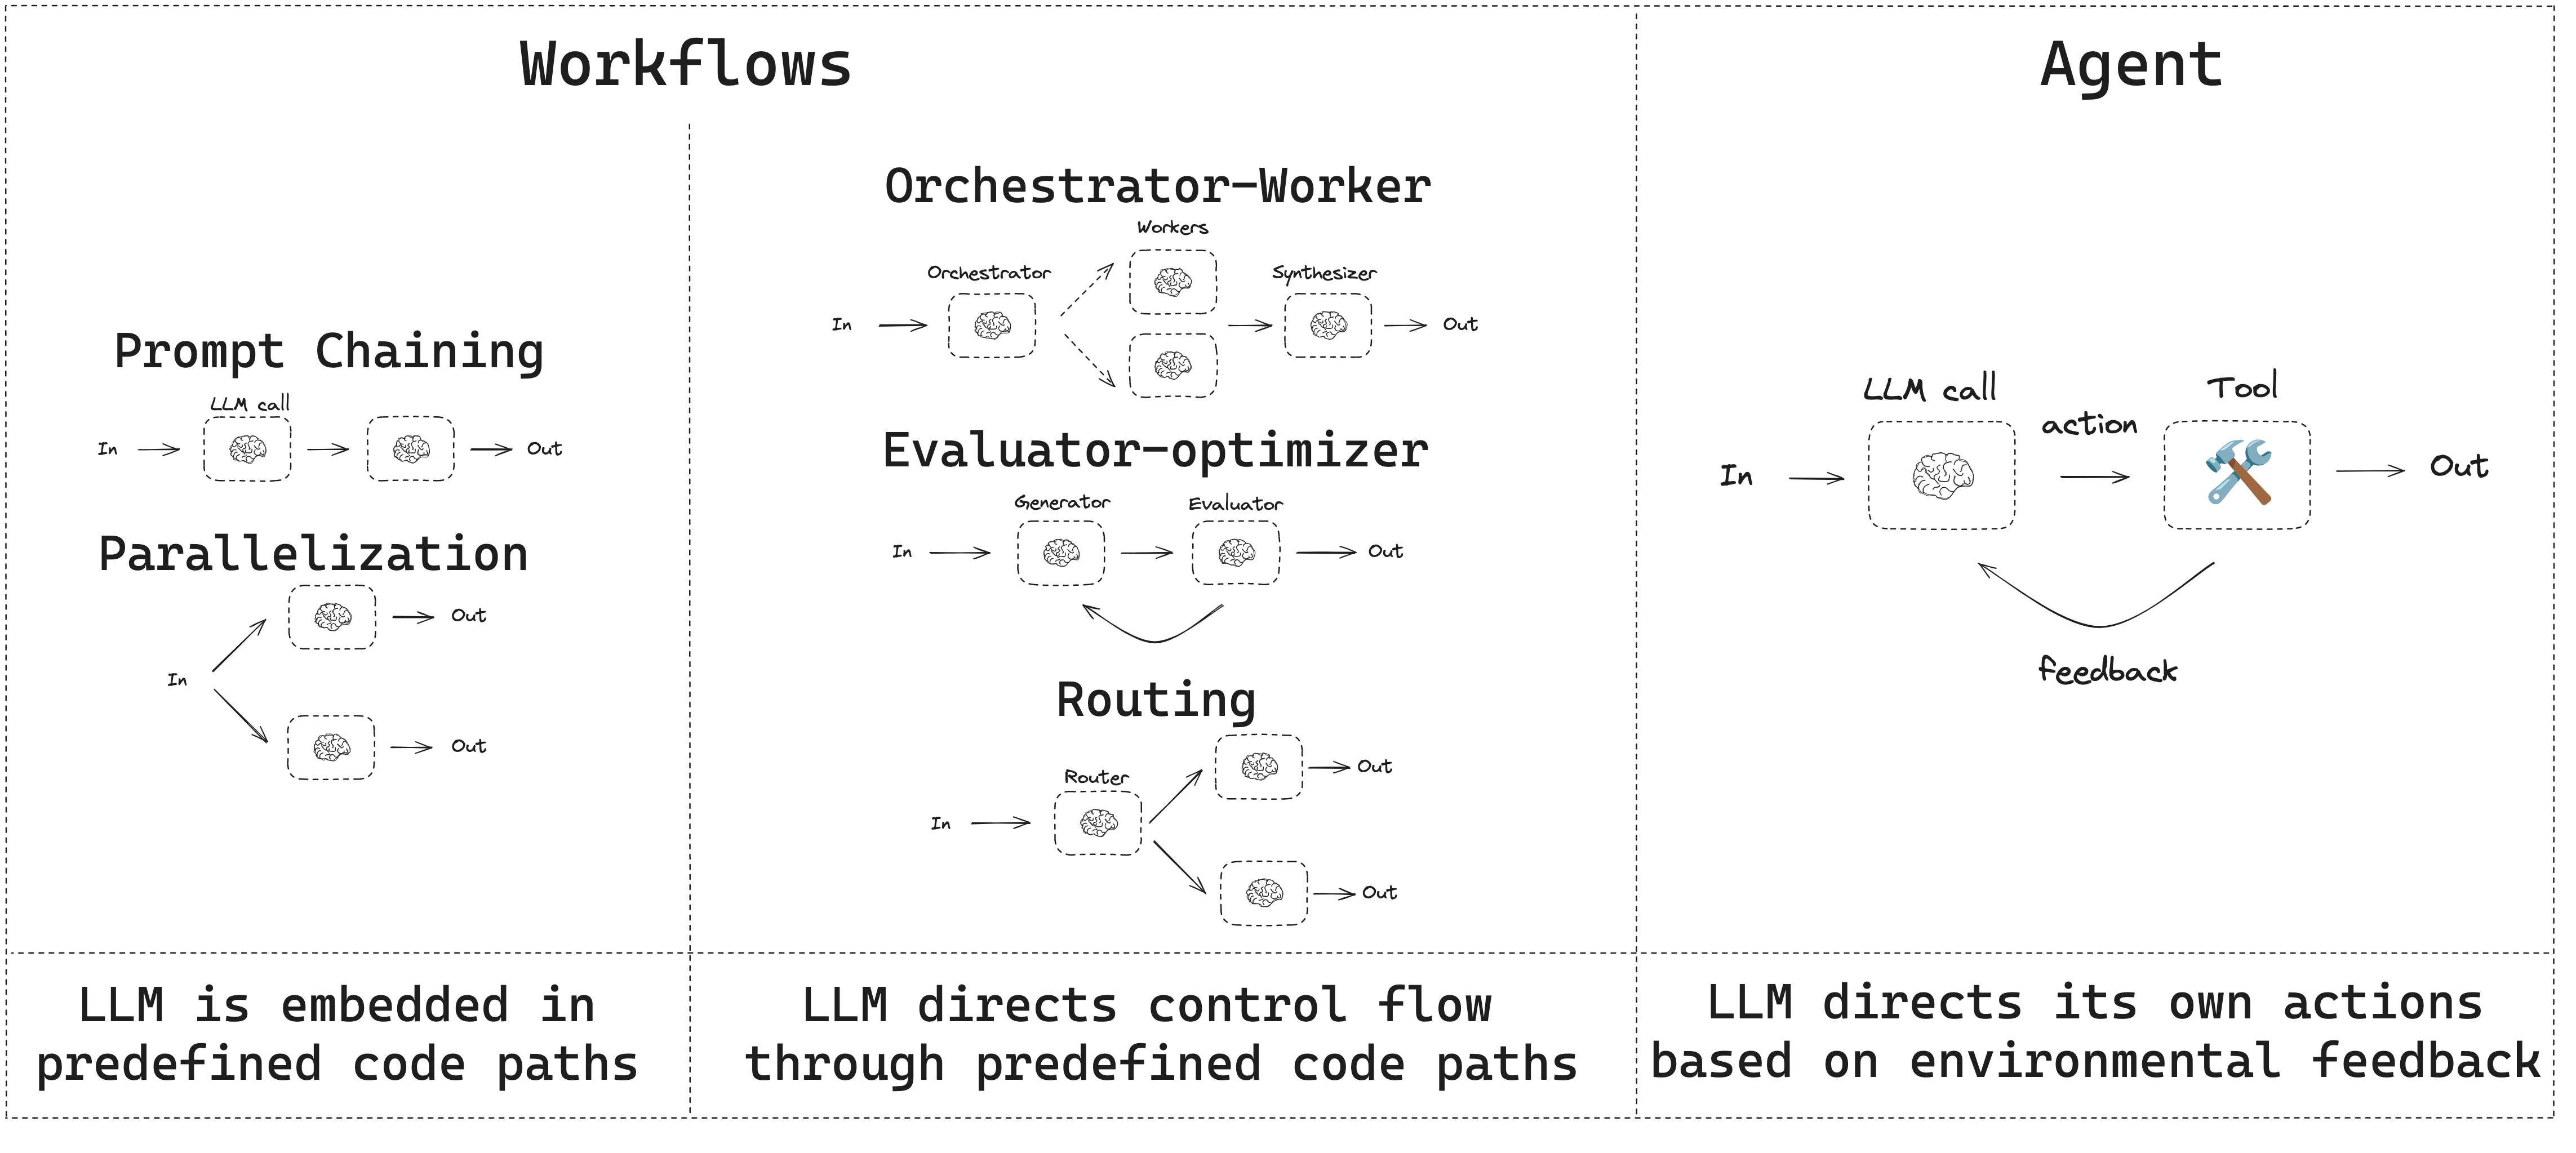
将此类流程模式与 LangSmith 进行对比。通过 追踪快速入门 查看数据如何在各步骤间流动。我们建议您同时配置 LangSmith 引擎,该引擎监控您的追踪、检测问题并推荐修复方案。
设置
要构建流程或智能体,可以使用支持结构化输出和工具调用的 任意对话模型。以下示例使用 Anthropic: :::python- 安装依赖项:
pip install langchain_core langchain-anthropic langgraph
- 初始化 LLM:
import os
import getpass

from langchain_anthropic import ChatAnthropic

def _set_env(var: str):
    if not os.environ.get(var):
        os.environ[var] = getpass.getpass(f"{var}: ")


_set_env("ANTHROPIC_API_KEY")

llm = ChatAnthropic(model="claude-sonnet-4-6")
- 安装依赖
npm install @langchain/langgraph @langchain/core
pnpm add @langchain/langgraph @langchain/core
yarn add @langchain/langgraph @langchain/core
bun add @langchain/langgraph @langchain/core
- 初始化 LLM:
import { ChatAnthropic } from "@langchain/anthropic";

const llm = new ChatAnthropic({
  model: "claude-sonnet-4-6",
  apiKey: "<your_anthropic_key>"
});
LLM 与增强手段
流程和智能体系统基于 LLM 及其增强功能。工具调用、结构化输出 和 短期记忆 是定制 LLM 的常见方式。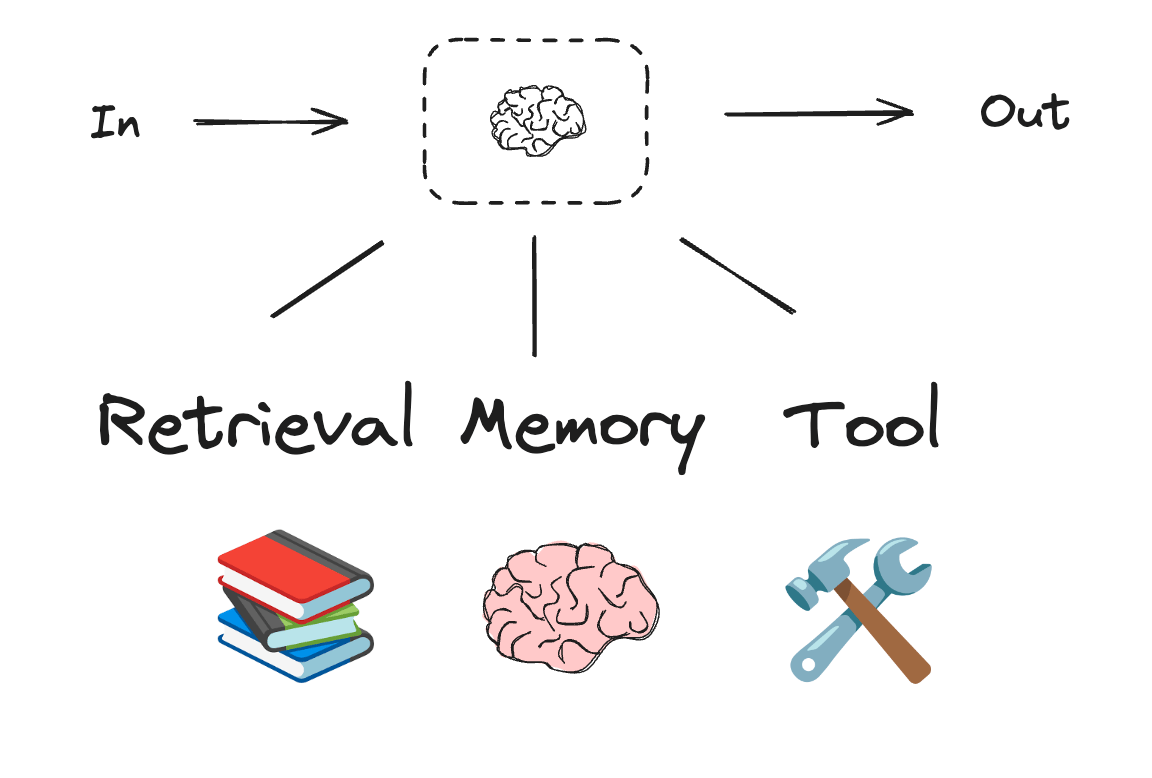
# Schema for structured output
from pydantic import BaseModel, Field


class SearchQuery(BaseModel):
    search_query: str | None = Field(
        default=None, description="Query that is optimized web search."
    )
    justification: str | None = Field(
        default=None, description="Why this query is relevant to the user's request."
    )


# Augment the LLM with schema for structured output
structured_llm = llm.with_structured_output(SearchQuery)

# Invoke the augmented LLM
output = structured_llm.invoke("How does Calcium CT score relate to high cholesterol?")
print(output)  # The model returns an instance of SearchQuery.

# Define a tool
def multiply(a: int, b: int) -> int:
    return a * b

# Augment the LLM with tools
llm_with_tools = llm.bind_tools([multiply])

# Invoke the LLM with input that triggers the tool call
msg = llm_with_tools.invoke("What is 2 times 3?")
print(msg.tool_calls)  # The model returns a request to call the tool.
import * as z from "zod";
import { tool } from "langchain";

// Schema for structured output
const SearchQuery = z.object({
  search_query: z.string().describe("Query that is optimized web search."),
  justification: z
    .string()
    .describe("Why this query is relevant to the user's request."),
});

// Augment the LLM with schema for structured output
const structuredLlm = llm.withStructuredOutput(SearchQuery);

// Invoke the augmented LLM
const output = await structuredLlm.invoke(
  "How does Calcium CT score relate to high cholesterol?"
);

// Define a tool
const multiply = tool(
  ({ a, b }) => {
    return a * b;
  },
  {
    name: "multiply",
    description: "Multiply two numbers",
    schema: z.object({
      a: z.number(),
      b: z.number(),
    }),
  }
);

// Augment the LLM with tools
const llmWithTools = llm.bindTools([multiply]);

// Invoke the LLM with input that triggers the tool call
const msg = await llmWithTools.invoke("What is 2 times 3?");

// Get the tool call
console.log(msg.tool_calls);
提示词链
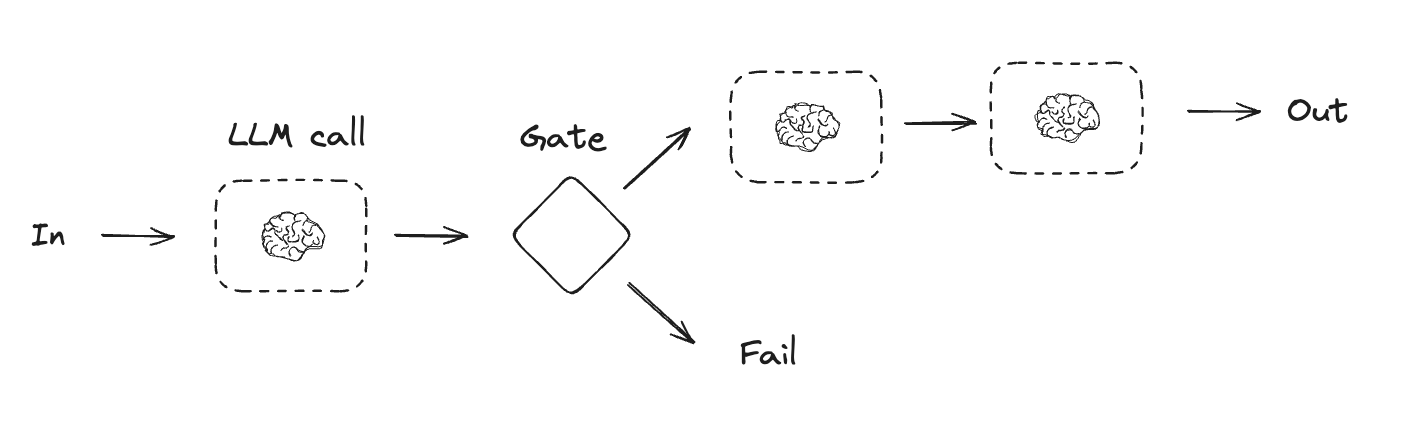
提示词串联是指每个 LLM 调用处理前一个调用的输出。常用于分解为可验证小步骤的明确任务,例如:- 将文档翻译为不同语言
- 验证生成内容的一致性
from typing_extensions import TypedDict
from langgraph.graph import StateGraph, START, END
from IPython.display import Image, display


# Graph state
class State(TypedDict):
    topic: str
    joke: str
    improved_joke: str
    final_joke: str


# Nodes
def generate_joke(state: State):
    """First LLM call to generate initial joke"""

    msg = llm.invoke(f"Write a short joke about {state['topic']}")
    return {"joke": msg.content}


def check_punchline(state: State):
    """Gate function to check if the joke has a punchline"""

    # Simple check - does the joke contain "?" or "!"
    if "?" in state["joke"] or "!" in state["joke"]:
        return "Pass"
    return "Fail"


def improve_joke(state: State):
    """Second LLM call to improve the joke"""

    msg = llm.invoke(f"Make this joke funnier by adding wordplay: {state['joke']}")
    return {"improved_joke": msg.content}


def polish_joke(state: State):
    """Third LLM call for final polish"""
    msg = llm.invoke(f"Add a surprising twist to this joke: {state['improved_joke']}")
    return {"final_joke": msg.content}


# Build workflow
workflow = StateGraph(State)

# Add nodes
workflow.add_node("generate_joke", generate_joke)
workflow.add_node("improve_joke", improve_joke)
workflow.add_node("polish_joke", polish_joke)

# Add edges to connect nodes
workflow.add_edge(START, "generate_joke")
workflow.add_conditional_edges(
    "generate_joke", check_punchline, {"Fail": "improve_joke", "Pass": END}
)
workflow.add_edge("improve_joke", "polish_joke")
workflow.add_edge("polish_joke", END)

# Compile
chain = workflow.compile()

# Show workflow
display(Image(chain.get_graph().draw_mermaid_png()))

# Invoke
state = chain.invoke({"topic": "cats"})
print("Initial joke:")
print(state["joke"])
print("\n--- --- ---\n")
if "improved_joke" in state:
    print("Improved joke:")
    print(state["improved_joke"])
    print("\n--- --- ---\n")

    print("Final joke:")
    print(state["final_joke"])
else:
    print("Final joke:")
    print(state["joke"])
from langgraph.func import entrypoint, task


# Tasks
@task
def generate_joke(topic: str):
    """First LLM call to generate initial joke"""
    msg = llm.invoke(f"Write a short joke about {topic}")
    return msg.content


def check_punchline(joke: str):
    """Gate function to check if the joke has a punchline"""
    # Simple check - does the joke contain "?" or "!"
    if "?" in joke or "!" in joke:
        return "Fail"

    return "Pass"


@task
def improve_joke(joke: str):
    """Second LLM call to improve the joke"""
    msg = llm.invoke(f"Make this joke funnier by adding wordplay: {joke}")
    return msg.content


@task
def polish_joke(joke: str):
    """Third LLM call for final polish"""
    msg = llm.invoke(f"Add a surprising twist to this joke: {joke}")
    return msg.content


@entrypoint()
def prompt_chaining_workflow(topic: str):
    original_joke = generate_joke(topic).result()
    if check_punchline(original_joke) == "Pass":
        return original_joke

    improved_joke = improve_joke(original_joke).result()
    return polish_joke(improved_joke).result()

# Invoke
stream = prompt_chaining_workflow.stream_events("cats", version="v3")
for snapshot in stream.values:
    print(snapshot)
    print("\n")
import { StateGraph, StateSchema, GraphNode, ConditionalEdgeRouter } from "@langchain/langgraph";
import { z } from "zod/v4";

// Graph state
const State = new StateSchema({
  topic: z.string(),
  joke: z.string(),
  improvedJoke: z.string(),
  finalJoke: z.string(),
});

// Define node functions

// First LLM call to generate initial joke
const generateJoke: GraphNode<typeof State> = async (state) => {
  const msg = await llm.invoke(`Write a short joke about ${state.topic}`);
  return { joke: msg.content };
};

// Gate function to check if the joke has a punchline
const checkPunchline: ConditionalEdgeRouter<{ InputSchema: typeof State; Nodes: "improveJoke" }> = (state) => {
  // Simple check - does the joke contain "?" or "!"
  if (state.joke?.includes("?") || state.joke?.includes("!")) {
    return "Pass";
  }
  return "Fail";
};

// Second LLM call to improve the joke
const improveJoke: GraphNode<typeof State> = async (state) => {
  const msg = await llm.invoke(
    `Make this joke funnier by adding wordplay: ${state.joke}`
  );
  return { improvedJoke: msg.content };
};

// Third LLM call for final polish
const polishJoke: GraphNode<typeof State> = async (state) => {
  const msg = await llm.invoke(
    `Add a surprising twist to this joke: ${state.improvedJoke}`
  );
  return { finalJoke: msg.content };
};

// Build workflow
const chain = new StateGraph(State)
  .addNode("generateJoke", generateJoke)
  .addNode("improveJoke", improveJoke)
  .addNode("polishJoke", polishJoke)
  .addEdge("__start__", "generateJoke")
  .addConditionalEdges("generateJoke", checkPunchline, {
    Pass: "improveJoke",
    Fail: "__end__"
  })
  .addEdge("improveJoke", "polishJoke")
  .addEdge("polishJoke", "__end__")
  .compile();

// Invoke
const state = await chain.invoke({ topic: "cats" });
console.log("Initial joke:");
console.log(state.joke);
console.log("\n--- --- ---\n");
if (state.improvedJoke !== undefined) {
  console.log("Improved joke:");
  console.log(state.improvedJoke);
  console.log("\n--- --- ---\n");

  console.log("Final joke:");
  console.log(state.finalJoke);
} else {
  console.log("Joke failed quality gate - no punchline detected!");
}
import { task, entrypoint } from "@langchain/langgraph";

// Tasks

// First LLM call to generate initial joke
const generateJoke = task("generateJoke", async (topic: string) => {
  const msg = await llm.invoke(`Write a short joke about ${topic}`);
  return msg.content;
});

// Gate function to check if the joke has a punchline
function checkPunchline(joke: string) {
  // Simple check - does the joke contain "?" or "!"
  if (joke.includes("?") || joke.includes("!")) {
    return "Pass";
  }
  return "Fail";
}

  // Second LLM call to improve the joke
const improveJoke = task("improveJoke", async (joke: string) => {
  const msg = await llm.invoke(
    `Make this joke funnier by adding wordplay: ${joke}`
  );
  return msg.content;
});

// Third LLM call for final polish
const polishJoke = task("polishJoke", async (joke: string) => {
  const msg = await llm.invoke(
    `Add a surprising twist to this joke: ${joke}`
  );
  return msg.content;
});

const workflow = entrypoint(
  "jokeMaker",
  async (topic: string) => {
    const originalJoke = await generateJoke(topic);
    if (checkPunchline(originalJoke) === "Pass") {
      return originalJoke;
    }
    const improvedJoke = await improveJoke(originalJoke);
    const polishedJoke = await polishJoke(improvedJoke);
    return polishedJoke;
  }
);

const stream = await workflow.streamEvents("cats", { version: "v3" });
for await (const snapshot of stream.values) {
  console.log(snapshot);
}
并行化
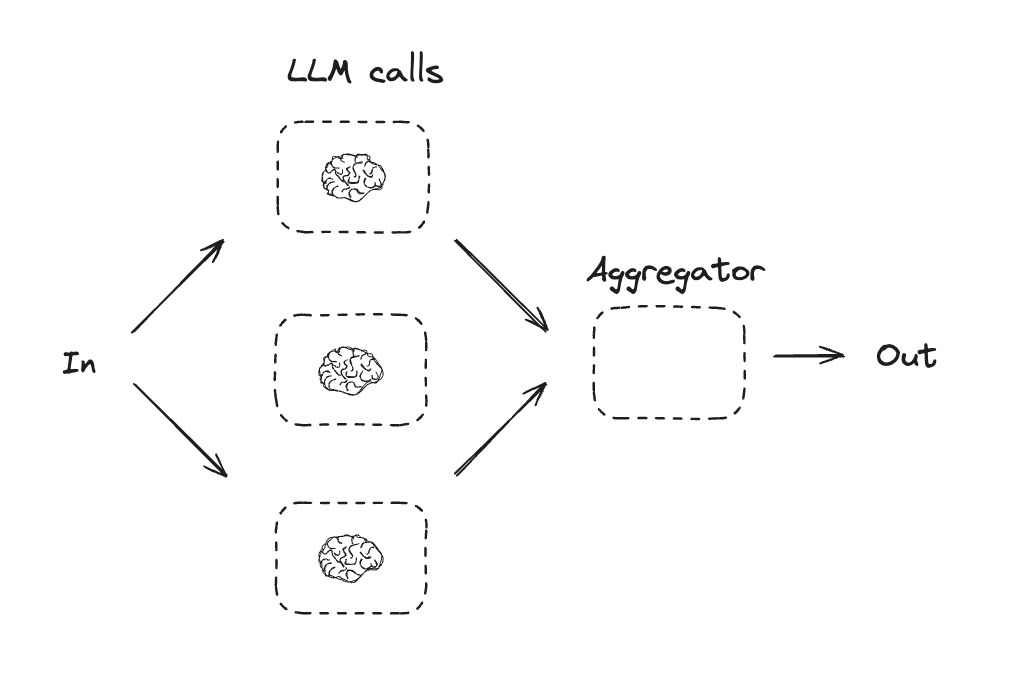
并行化使 LLMs 同时处理任务,可通过运行多个独立子任务或重复执行同一任务实现。常见场景包括:- 分解子任务并行执行以提升速度
- 多次执行任务以验证不同输出以增强信心
- 第一个子任务处理文档关键词,第二个子任务检查格式错误
- 多次执行评分任务,基于不同标准(如引用数量、来源数量、来源质量)评估文档准确性
# Graph state
class State(TypedDict):
    topic: str
    joke: str
    story: str
    poem: str
    combined_output: str


# Nodes
def call_llm_1(state: State):
    """First LLM call to generate initial joke"""

    msg = llm.invoke(f"Write a joke about {state['topic']}")
    return {"joke": msg.content}


def call_llm_2(state: State):
    """Second LLM call to generate story"""

    msg = llm.invoke(f"Write a story about {state['topic']}")
    return {"story": msg.content}


def call_llm_3(state: State):
    """Third LLM call to generate poem"""

    msg = llm.invoke(f"Write a poem about {state['topic']}")
    return {"poem": msg.content}


def aggregator(state: State):
    """Combine the joke, story and poem into a single output"""

    combined = f"Here's a story, joke, and poem about {state['topic']}!\n\n"
    combined += f"STORY:\n{state['story']}\n\n"
    combined += f"JOKE:\n{state['joke']}\n\n"
    combined += f"POEM:\n{state['poem']}"
    return {"combined_output": combined}


# Build workflow
parallel_builder = StateGraph(State)

# Add nodes
parallel_builder.add_node("call_llm_1", call_llm_1)
parallel_builder.add_node("call_llm_2", call_llm_2)
parallel_builder.add_node("call_llm_3", call_llm_3)
parallel_builder.add_node("aggregator", aggregator)

# Add edges to connect nodes
parallel_builder.add_edge(START, "call_llm_1")
parallel_builder.add_edge(START, "call_llm_2")
parallel_builder.add_edge(START, "call_llm_3")
parallel_builder.add_edge("call_llm_1", "aggregator")
parallel_builder.add_edge("call_llm_2", "aggregator")
parallel_builder.add_edge("call_llm_3", "aggregator")
parallel_builder.add_edge("aggregator", END)
parallel_workflow = parallel_builder.compile()

# Show workflow
display(Image(parallel_workflow.get_graph().draw_mermaid_png()))

# Invoke
state = parallel_workflow.invoke({"topic": "cats"})
print(state["combined_output"])
@task
def call_llm_1(topic: str):
    """First LLM call to generate initial joke"""
    msg = llm.invoke(f"Write a joke about {topic}")
    return msg.content


@task
def call_llm_2(topic: str):
    """Second LLM call to generate story"""
    msg = llm.invoke(f"Write a story about {topic}")
    return msg.content


@task
def call_llm_3(topic):
    """Third LLM call to generate poem"""
    msg = llm.invoke(f"Write a poem about {topic}")
    return msg.content


@task
def aggregator(topic, joke, story, poem):
    """Combine the joke and story into a single output"""

    combined = f"Here's a story, joke, and poem about {topic}!\n\n"
    combined += f"STORY:\n{story}\n\n"
    combined += f"JOKE:\n{joke}\n\n"
    combined += f"POEM:\n{poem}"
    return combined


# Build workflow
@entrypoint()
def parallel_workflow(topic: str):
    joke_fut = call_llm_1(topic)
    story_fut = call_llm_2(topic)
    poem_fut = call_llm_3(topic)
    return aggregator(
        topic, joke_fut.result(), story_fut.result(), poem_fut.result()
    ).result()

# Invoke
stream = parallel_workflow.stream_events("cats", version="v3")
for snapshot in stream.values:
    print(snapshot)
    print("\n")
import { StateGraph, StateSchema, GraphNode } from "@langchain/langgraph";
import * as z from "zod";

// Graph state
const State = new StateSchema({
  topic: z.string(),
  joke: z.string(),
  story: z.string(),
  poem: z.string(),
  combinedOutput: z.string(),
});

// Nodes
// First LLM call to generate initial joke
const callLlm1: GraphNode<typeof State> = async (state) => {
  const msg = await llm.invoke(`Write a joke about ${state.topic}`);
  return { joke: msg.content };
};

// Second LLM call to generate story
const callLlm2: GraphNode<typeof State> = async (state) => {
  const msg = await llm.invoke(`Write a story about ${state.topic}`);
  return { story: msg.content };
};

// Third LLM call to generate poem
const callLlm3: GraphNode<typeof State> = async (state) => {
  const msg = await llm.invoke(`Write a poem about ${state.topic}`);
  return { poem: msg.content };
};

// Combine the joke, story and poem into a single output
const aggregator: GraphNode<typeof State> = async (state) => {
  const combined = `Here's a story, joke, and poem about ${state.topic}!\n\n` +
    `STORY:\n${state.story}\n\n` +
    `JOKE:\n${state.joke}\n\n` +
    `POEM:\n${state.poem}`;
  return { combinedOutput: combined };
};

// Build workflow
const parallelWorkflow = new StateGraph(State)
  .addNode("callLlm1", callLlm1)
  .addNode("callLlm2", callLlm2)
  .addNode("callLlm3", callLlm3)
  .addNode("aggregator", aggregator)
  .addEdge("__start__", "callLlm1")
  .addEdge("__start__", "callLlm2")
  .addEdge("__start__", "callLlm3")
  .addEdge("callLlm1", "aggregator")
  .addEdge("callLlm2", "aggregator")
  .addEdge("callLlm3", "aggregator")
  .addEdge("aggregator", "__end__")
  .compile();

// Invoke
const result = await parallelWorkflow.invoke({ topic: "cats" });
console.log(result.combinedOutput);
import { task, entrypoint } from "@langchain/langgraph";

// Tasks

// First LLM call to generate initial joke
const callLlm1 = task("generateJoke", async (topic: string) => {
  const msg = await llm.invoke(`Write a joke about ${topic}`);
  return msg.content;
});

// Second LLM call to generate story
const callLlm2 = task("generateStory", async (topic: string) => {
  const msg = await llm.invoke(`Write a story about ${topic}`);
  return msg.content;
});

// Third LLM call to generate poem
const callLlm3 = task("generatePoem", async (topic: string) => {
  const msg = await llm.invoke(`Write a poem about ${topic}`);
  return msg.content;
});

// Combine outputs
const aggregator = task("aggregator", async (params: {
  topic: string;
  joke: string;
  story: string;
  poem: string;
}) => {
  const { topic, joke, story, poem } = params;
  return `Here's a story, joke, and poem about ${topic}!\n\n` +
    `STORY:\n${story}\n\n` +
    `JOKE:\n${joke}\n\n` +
    `POEM:\n${poem}`;
});

// Build workflow
const workflow = entrypoint(
  "parallelWorkflow",
  async (topic: string) => {
    const [joke, story, poem] = await Promise.all([
      callLlm1(topic),
      callLlm2(topic),
      callLlm3(topic),
    ]);

    return aggregator({ topic, joke, story, poem });
  }
);

// Invoke
const stream = await workflow.streamEvents("cats", { version: "v3" });
for await (const snapshot of stream.values) {
  console.log(snapshot);
}
路由
路由工作流处理输入并将其导向上下文特定的任务。这允许您为复杂任务定义专用流程。例如,一个用于回答产品相关问题的工作流可能首先处理问题类型,然后将请求路由到定价、退款、退货等特定处理流程。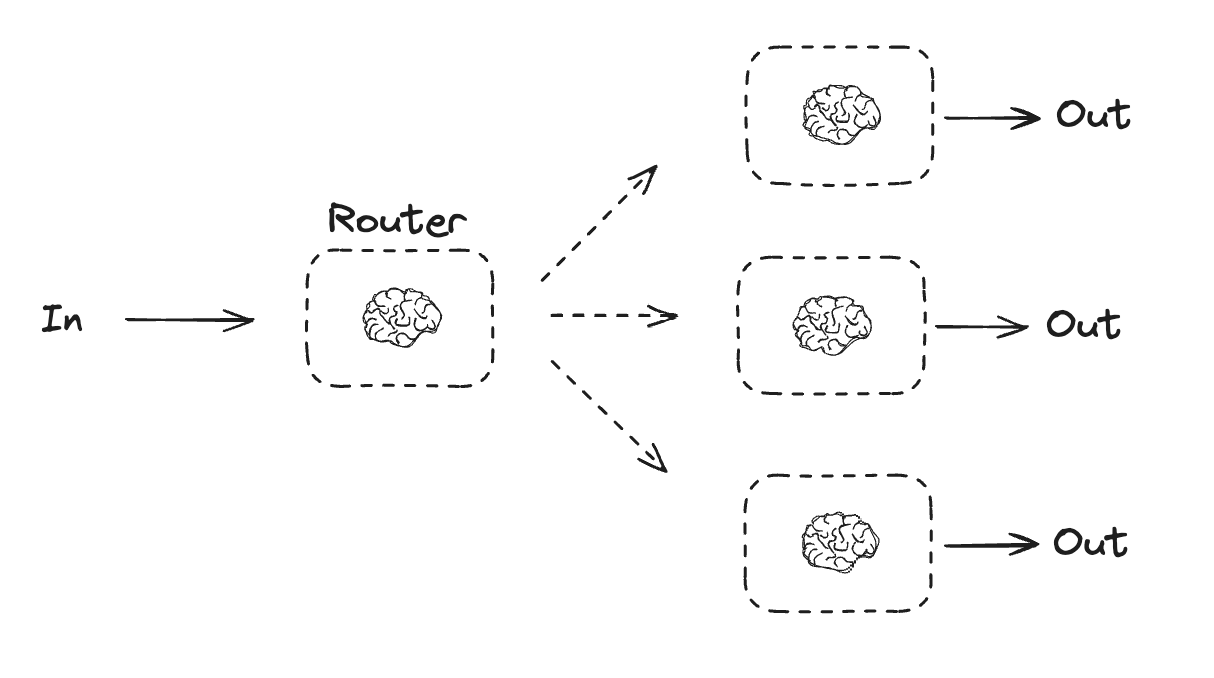
from typing_extensions import Literal
from langchain.messages import HumanMessage, SystemMessage


# Schema for structured output to use as routing logic
class Route(BaseModel):
    step: Literal["poem", "story", "joke"] = Field(
        None, description="The next step in the routing process"
    )


# Augment the LLM with schema for structured output
router = llm.with_structured_output(Route)


# State
class State(TypedDict):
    input: str
    decision: str
    output: str


# Nodes
def llm_call_1(state: State):
    """Write a story"""

    result = llm.invoke(state["input"])
    return {"output": result.content}


def llm_call_2(state: State):
    """Write a joke"""

    result = llm.invoke(state["input"])
    return {"output": result.content}


def llm_call_3(state: State):
    """Write a poem"""

    result = llm.invoke(state["input"])
    return {"output": result.content}


def llm_call_router(state: State):
    """Route the input to the appropriate node"""

    # Run the augmented LLM with structured output to serve as routing logic
    decision = router.invoke(
        [
            SystemMessage(
                content="Route the input to story, joke, or poem based on the user's request."
            ),
            HumanMessage(content=state["input"]),
        ]
    )

    return {"decision": decision.step}


# Conditional edge function to route to the appropriate node
def route_decision(state: State):
    # Return the node name you want to visit next
    if state["decision"] == "story":
        return "llm_call_1"
    elif state["decision"] == "joke":
        return "llm_call_2"
    elif state["decision"] == "poem":
        return "llm_call_3"


# Build workflow
router_builder = StateGraph(State)

# Add nodes
router_builder.add_node("llm_call_1", llm_call_1)
router_builder.add_node("llm_call_2", llm_call_2)
router_builder.add_node("llm_call_3", llm_call_3)
router_builder.add_node("llm_call_router", llm_call_router)

# Add edges to connect nodes
router_builder.add_edge(START, "llm_call_router")
router_builder.add_conditional_edges(
    "llm_call_router",
    route_decision,
    {  # Name returned by route_decision : Name of next node to visit
        "llm_call_1": "llm_call_1",
        "llm_call_2": "llm_call_2",
        "llm_call_3": "llm_call_3",
    },
)
router_builder.add_edge("llm_call_1", END)
router_builder.add_edge("llm_call_2", END)
router_builder.add_edge("llm_call_3", END)

# Compile workflow
router_workflow = router_builder.compile()

# Show the workflow
display(Image(router_workflow.get_graph().draw_mermaid_png()))

# Invoke
state = router_workflow.invoke({"input": "Write me a joke about cats"})
print(state["output"])
from typing_extensions import Literal
from pydantic import BaseModel
from langchain.messages import HumanMessage, SystemMessage


# Schema for structured output to use as routing logic
class Route(BaseModel):
    step: Literal["poem", "story", "joke"] = Field(
        None, description="The next step in the routing process"
    )


# Augment the LLM with schema for structured output
router = llm.with_structured_output(Route)


@task
def llm_call_1(input_: str):
    """Write a story"""
    result = llm.invoke(input_)
    return result.content


@task
def llm_call_2(input_: str):
    """Write a joke"""
    result = llm.invoke(input_)
    return result.content


@task
def llm_call_3(input_: str):
    """Write a poem"""
    result = llm.invoke(input_)
    return result.content


def llm_call_router(input_: str):
    """Route the input to the appropriate node"""
    # Run the augmented LLM with structured output to serve as routing logic
    decision = router.invoke(
        [
            SystemMessage(
                content="Route the input to story, joke, or poem based on the user's request."
            ),
            HumanMessage(content=input_),
        ]
    )
    return decision.step


# Create workflow
@entrypoint()
def router_workflow(input_: str):
    next_step = llm_call_router(input_)
    if next_step == "story":
        llm_call = llm_call_1
    elif next_step == "joke":
        llm_call = llm_call_2
    elif next_step == "poem":
        llm_call = llm_call_3

    return llm_call(input_).result()

# Invoke
stream = router_workflow.stream_events("Write me a joke about cats", version="v3")
for snapshot in stream.values:
    print(snapshot)
    print("\n")
import { StateGraph, StateSchema, GraphNode, ConditionalEdgeRouter } from "@langchain/langgraph";
import * as z from "zod";

// Schema for structured output to use as routing logic
const routeSchema = z.object({
  step: z.enum(["poem", "story", "joke"]).describe(
    "The next step in the routing process"
  ),
});

// Augment the LLM with schema for structured output
const router = llm.withStructuredOutput(routeSchema);

// Graph state
const State = new StateSchema({
  input: z.string(),
  decision: z.string(),
  output: z.string(),
});

// Nodes
// Write a story
const llmCall1: GraphNode<typeof State> = async (state) => {
  const result = await llm.invoke([{
    role: "system",
    content: "You are an expert storyteller.",
  }, {
    role: "user",
    content: state.input
  }]);
  return { output: result.content };
};

// Write a joke
const llmCall2: GraphNode<typeof State> = async (state) => {
  const result = await llm.invoke([{
    role: "system",
    content: "You are an expert comedian.",
  }, {
    role: "user",
    content: state.input
  }]);
  return { output: result.content };
};

// Write a poem
const llmCall3: GraphNode<typeof State> = async (state) => {
  const result = await llm.invoke([{
    role: "system",
    content: "You are an expert poet.",
  }, {
    role: "user",
    content: state.input
  }]);
  return { output: result.content };
};

const llmCallRouter: GraphNode<typeof State> = async (state) => {
  // Route the input to the appropriate node
  const decision = await router.invoke([
    {
      role: "system",
      content: "Route the input to story, joke, or poem based on the user's request."
    },
    {
      role: "user",
      content: state.input
    },
  ]);

  return { decision: decision.step };
};

// Conditional edge function to route to the appropriate node
const routeDecision: ConditionalEdgeRouter<{ InputSchema: typeof State; Nodes: "llmCall1" | "llmCall2" | "llmCall3" }> = (state) => {
  // Return the node name you want to visit next
  if (state.decision === "story") {
    return "llmCall1";
  } else if (state.decision === "joke") {
    return "llmCall2";
  } else {
    return "llmCall3";
  }
};

// Build workflow
const routerWorkflow = new StateGraph(State)
  .addNode("llmCall1", llmCall1)
  .addNode("llmCall2", llmCall2)
  .addNode("llmCall3", llmCall3)
  .addNode("llmCallRouter", llmCallRouter)
  .addEdge("__start__", "llmCallRouter")
  .addConditionalEdges(
    "llmCallRouter",
    routeDecision,
    ["llmCall1", "llmCall2", "llmCall3"],
  )
  .addEdge("llmCall1", "__end__")
  .addEdge("llmCall2", "__end__")
  .addEdge("llmCall3", "__end__")
  .compile();

// Invoke
const state = await routerWorkflow.invoke({
  input: "Write me a joke about cats"
});
console.log(state.output);
import * as z from "zod";
import { task, entrypoint } from "@langchain/langgraph";

// Schema for structured output to use as routing logic
const routeSchema = z.object({
  step: z.enum(["poem", "story", "joke"]).describe(
    "The next step in the routing process"
  ),
});

// Augment the LLM with schema for structured output
const router = llm.withStructuredOutput(routeSchema);

// Tasks
// Write a story
const llmCall1 = task("generateStory", async (input: string) => {
  const result = await llm.invoke([{
    role: "system",
    content: "You are an expert storyteller.",
  }, {
    role: "user",
    content: input
  }]);
  return result.content;
});

// Write a joke
const llmCall2 = task("generateJoke", async (input: string) => {
  const result = await llm.invoke([{
    role: "system",
    content: "You are an expert comedian.",
  }, {
    role: "user",
    content: input
  }]);
  return result.content;
});

// Write a poem
const llmCall3 = task("generatePoem", async (input: string) => {
  const result = await llm.invoke([{
    role: "system",
    content: "You are an expert poet.",
  }, {
    role: "user",
    content: input
  }]);
  return result.content;
});

// Route the input to the appropriate node
const llmCallRouter = task("router", async (input: string) => {
  const decision = await router.invoke([
    {
      role: "system",
      content: "Route the input to story, joke, or poem based on the user's request."
    },
    {
      role: "user",
      content: input
    },
  ]);
  return decision.step;
});

// Build workflow
const workflow = entrypoint(
  "routerWorkflow",
  async (input: string) => {
    const nextStep = await llmCallRouter(input);

    let llmCall;
    if (nextStep === "story") {
      llmCall = llmCall1;
    } else if (nextStep === "joke") {
      llmCall = llmCall2;
    } else if (nextStep === "poem") {
      llmCall = llmCall3;
    }

    const finalResult = await llmCall(input);
    return finalResult;
  }
);

// Invoke
const stream = await workflow.streamEvents("Write me a joke about cats", { version: "v3" });
for await (const snapshot of stream.values) {
  console.log(snapshot);
}
调度器-工作节点
在调度器-工作节点配置中,调度器:- 将任务分解为子任务
- 将子任务委托给工作节点
- 将工作节点输出合成最终结果
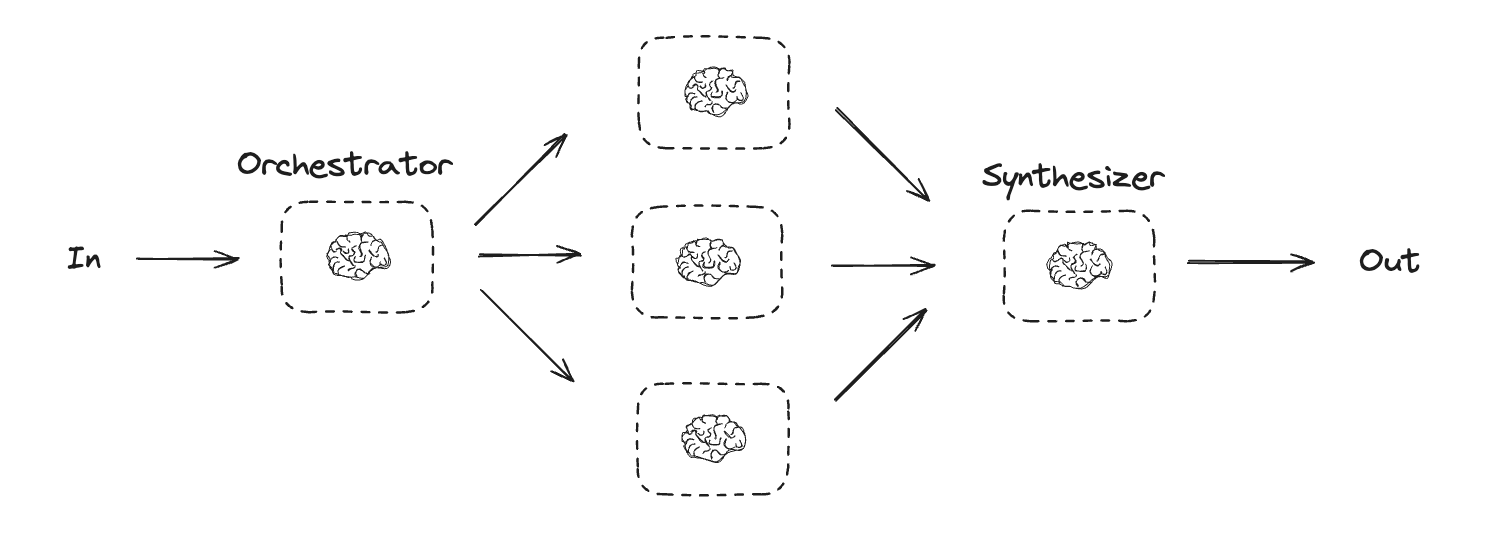
from typing import Annotated, List
import operator


# Schema for structured output to use in planning
class Section(BaseModel):
    name: str = Field(
        description="Name for this section of the report.",
    )
    description: str = Field(
        description="Brief overview of the main topics and concepts to be covered in this section.",
    )


class Sections(BaseModel):
    sections: List[Section] = Field(
        description="Sections of the report.",
    )


# Augment the LLM with schema for structured output
planner = llm.with_structured_output(Sections)
from typing import List


# Schema for structured output to use in planning
class Section(BaseModel):
    name: str = Field(
        description="Name for this section of the report.",
    )
    description: str = Field(
        description="Brief overview of the main topics and concepts to be covered in this section.",
    )


class Sections(BaseModel):
    sections: List[Section] = Field(
        description="Sections of the report.",
    )


# Augment the LLM with schema for structured output
planner = llm.with_structured_output(Sections)


@task
def orchestrator(topic: str):
    """Orchestrator that generates a plan for the report"""
    # Generate queries
    report_sections = planner.invoke(
        [
            SystemMessage(content="Generate a plan for the report."),
            HumanMessage(content=f"Here is the report topic: {topic}"),
        ]
    )

    return report_sections.sections


@task
def llm_call(section: Section):
    """Worker writes a section of the report"""

    # Generate section
    result = llm.invoke(
        [
            SystemMessage(content="Write a report section."),
            HumanMessage(
                content=f"Here is the section name: {section.name} and description: {section.description}"
            ),
        ]
    )

    # Write the updated section to completed sections
    return result.content


@task
def synthesizer(completed_sections: list[str]):
    """Synthesize full report from sections"""
    final_report = "\n\n---\n\n".join(completed_sections)
    return final_report


@entrypoint()
def orchestrator_worker(topic: str):
    sections = orchestrator(topic).result()
    section_futures = [llm_call(section) for section in sections]
    final_report = synthesizer(
        [section_fut.result() for section_fut in section_futures]
    ).result()
    return final_report

# Invoke
report = orchestrator_worker.invoke("Create a report on LLM scaling laws")
from IPython.display import Markdown
Markdown(report)
type SectionSchema = {
    name: string;
    description: string;
}
type SectionsSchema = {
    sections: SectionSchema[];
}

// Augment the LLM with schema for structured output
const planner = llm.withStructuredOutput(sectionsSchema);
import * as z from "zod";
import { task, entrypoint } from "@langchain/langgraph";

// Schema for structured output to use in planning
const sectionSchema = z.object({
  name: z.string().describe("Name for this section of the report."),
  description: z.string().describe(
    "Brief overview of the main topics and concepts to be covered in this section."
  ),
});

const sectionsSchema = z.object({
  sections: z.array(sectionSchema).describe("Sections of the report."),
});

// Augment the LLM with schema for structured output
const planner = llm.withStructuredOutput(sectionsSchema);

// Tasks
const orchestrator = task("orchestrator", async (topic: string) => {
  // Generate queries
  const reportSections = await planner.invoke([
    { role: "system", content: "Generate a plan for the report." },
    { role: "user", content: `Here is the report topic: ${topic}` },
  ]);

  return reportSections.sections;
});

const llmCall = task("sectionWriter", async (section: z.infer<typeof sectionSchema>) => {
  // Generate section
  const result = await llm.invoke([
    {
      role: "system",
      content: "Write a report section.",
    },
    {
      role: "user",
      content: `Here is the section name: ${section.name} and description: ${section.description}`,
    },
  ]);

  return result.content;
});

const synthesizer = task("synthesizer", async (completedSections: string[]) => {
  // Synthesize full report from sections
  return completedSections.join("\n\n---\n\n");
});

// Build workflow
const workflow = entrypoint(
  "orchestratorWorker",
  async (topic: string) => {
    const sections = await orchestrator(topic);
    const completedSections = await Promise.all(
      sections.map((section) => llmCall(section))
    );
    return synthesizer(completedSections);
  }
);

// Invoke
const stream = await workflow.streamEvents("Create a report on LLM scaling laws", { version: "v3" });
for await (const snapshot of stream.values) {
  console.log(snapshot);
}
在LangGraph中创建工作节点
LangGraph内置了对调度器-工作节点工作流的支持。Send API允许动态创建工作节点并为其传递特定输入。每个工作节点拥有独立状态,所有输出会写入共享状态键,供调度器图访问。这使调度器能获取所有工作节点输出并合成最终结果。下例通过Send API将列表中的每个章节发送给工作节点处理。
:::python
from langgraph.types import Send


# Graph state
class State(TypedDict):
    topic: str  # Report topic
    sections: list[Section]  # List of report sections
    completed_sections: Annotated[
        list, operator.add
    ]  # All workers write to this key in parallel
    final_report: str  # Final report


# Worker state
class WorkerState(TypedDict):
    section: Section
    completed_sections: Annotated[list, operator.add]


# Nodes
def orchestrator(state: State):
    """Orchestrator that generates a plan for the report"""

    # Generate queries
    report_sections = planner.invoke(
        [
            SystemMessage(content="Generate a plan for the report."),
            HumanMessage(content=f"Here is the report topic: {state['topic']}"),
        ]
    )

    return {"sections": report_sections.sections}


def llm_call(state: WorkerState):
    """Worker writes a section of the report"""

    # Generate section
    section = llm.invoke(
        [
            SystemMessage(
                content="Write a report section following the provided name and description. Include no preamble for each section. Use markdown formatting."
            ),
            HumanMessage(
                content=f"Here is the section name: {state['section'].name} and description: {state['section'].description}"
            ),
        ]
    )

    # Write the updated section to completed sections
    return {"completed_sections": [section.content]}


def synthesizer(state: State):
    """Synthesize full report from sections"""

    # List of completed sections
    completed_sections = state["completed_sections"]

    # Format completed section to str to use as context for final sections
    completed_report_sections = "\n\n---\n\n".join(completed_sections)

    return {"final_report": completed_report_sections}


# Conditional edge function to create llm_call workers that each write a section of the report
def assign_workers(state: State):
    """Assign a worker to each section in the plan"""

    # Kick off section writing in parallel via Send() API
    return [Send("llm_call", {"section": s}) for s in state["sections"]]


# Build workflow
orchestrator_worker_builder = StateGraph(State)

# Add the nodes
orchestrator_worker_builder.add_node("orchestrator", orchestrator)
orchestrator_worker_builder.add_node("llm_call", llm_call)
orchestrator_worker_builder.add_node("synthesizer", synthesizer)

# Add edges to connect nodes
orchestrator_worker_builder.add_edge(START, "orchestrator")
orchestrator_worker_builder.add_conditional_edges(
    "orchestrator", assign_workers, ["llm_call"]
)
orchestrator_worker_builder.add_edge("llm_call", "synthesizer")
orchestrator_worker_builder.add_edge("synthesizer", END)

# Compile the workflow
orchestrator_worker = orchestrator_worker_builder.compile()

# Show the workflow
display(Image(orchestrator_worker.get_graph().draw_mermaid_png()))

# Invoke
state = orchestrator_worker.invoke({"topic": "Create a report on LLM scaling laws"})

from IPython.display import Markdown
Markdown(state["final_report"])
import { StateGraph, StateSchema, ReducedValue, GraphNode, Send } from "@langchain/langgraph";
import * as z from "zod";

// Graph state
const State = new StateSchema({
  topic: z.string(),
  sections: z.array(z.custom<SectionsSchema>()),
  completedSections: new ReducedValue(
    z.array(z.string()).default(() => []),
    { reducer: (a, b) => a.concat(b) }
  ),
  finalReport: z.string(),
});

// Worker state
const WorkerState = new StateSchema({
  section: z.custom<SectionsSchema>(),
  completedSections: new ReducedValue(
    z.array(z.string()).default(() => []),
    { reducer: (a, b) => a.concat(b) }
  ),
});

// Nodes
const orchestrator: GraphNode<typeof State> = async (state) => {
  // Generate queries
  const reportSections = await planner.invoke([
    { role: "system", content: "Generate a plan for the report." },
    { role: "user", content: `Here is the report topic: ${state.topic}` },
  ]);

  return { sections: reportSections.sections };
};

const llmCall: GraphNode<typeof WorkerState> = async (state) => {
  // Generate section
  const section = await llm.invoke([
    {
      role: "system",
      content: "Write a report section following the provided name and description. Include no preamble for each section. Use markdown formatting.",
    },
    {
      role: "user",
      content: `Here is the section name: ${state.section.name} and description: ${state.section.description}`,
    },
  ]);

  // Write the updated section to completed sections
  return { completedSections: [section.content] };
};

const synthesizer: GraphNode<typeof State> = async (state) => {
  // List of completed sections
  const completedSections = state.completedSections;

  // Format completed section to str to use as context for final sections
  const completedReportSections = completedSections.join("\n\n---\n\n");

  return { finalReport: completedReportSections };
};

// Conditional edge function to create llm_call workers that each write a section of the report
const assignWorkers: ConditionalEdgeRouter<{ InputSchema: typeof State; Nodes: "llmCall" }> = (state) => {
  // Kick off section writing in parallel via Send() API
  return state.sections.map((section) =>
    new Send("llmCall", { section })
  );
};

// Build workflow
const orchestratorWorker = new StateGraph(State)
  .addNode("orchestrator", orchestrator)
  .addNode("llmCall", llmCall)
  .addNode("synthesizer", synthesizer)
  .addEdge("__start__", "orchestrator")
  .addConditionalEdges(
    "orchestrator",
    assignWorkers,
    ["llmCall"]
  )
  .addEdge("llmCall", "synthesizer")
  .addEdge("synthesizer", "__end__")
  .compile();

// Invoke
const state = await orchestratorWorker.invoke({
  topic: "Create a report on LLM scaling laws"
});
console.log(state.finalReport);
评估器-优化器
评估器-优化器工作流中,一个LLM调用生成响应,另一个评估该响应。若评估器或人工审核介入判定响应需优化,则提供反馈并重新生成。此循环持续至生成可接受响应。 评估器-优化器工作流常用于存在明确成功标准但需迭代优化的任务。例如,跨语言文本翻译可能需多次迭代才能确保语义一致。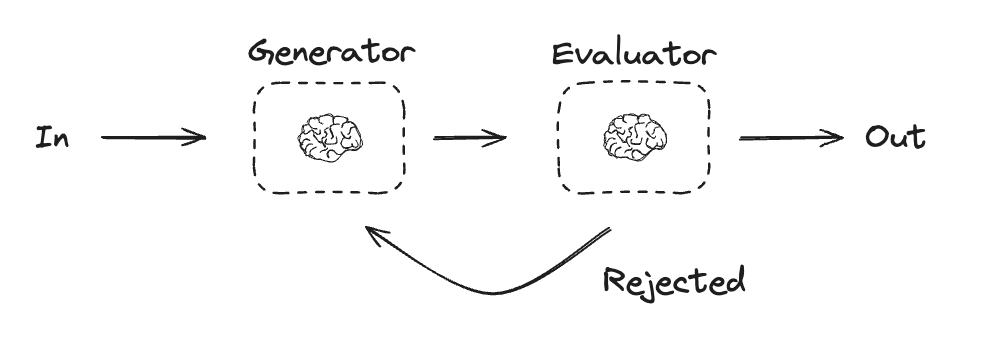
# Graph state
class State(TypedDict):
    joke: str
    topic: str
    feedback: str
    funny_or_not: str


# Schema for structured output to use in evaluation
class Feedback(BaseModel):
    grade: Literal["funny", "not funny"] = Field(
        description="Decide if the joke is funny or not.",
    )
    feedback: str = Field(
        description="If the joke is not funny, provide feedback on how to improve it.",
    )


# Augment the LLM with schema for structured output
evaluator = llm.with_structured_output(Feedback)


# Nodes
def llm_call_generator(state: State):
    """LLM generates a joke"""

    if state.get("feedback"):
        msg = llm.invoke(
            f"Write a joke about {state['topic']} but take into account the feedback: {state['feedback']}"
        )
    else:
        msg = llm.invoke(f"Write a joke about {state['topic']}")
    return {"joke": msg.content}


def llm_call_evaluator(state: State):
    """LLM evaluates the joke"""

    grade = evaluator.invoke(f"Grade the joke {state['joke']}")
    return {"funny_or_not": grade.grade, "feedback": grade.feedback}


# Conditional edge function to route back to joke generator or end based upon feedback from the evaluator
def route_joke(state: State):
    """Route back to joke generator or end based upon feedback from the evaluator"""

    if state["funny_or_not"] == "funny":
        return "Accepted"
    elif state["funny_or_not"] == "not funny":
        return "Rejected + Feedback"


# Build workflow
optimizer_builder = StateGraph(State)

# Add the nodes
optimizer_builder.add_node("llm_call_generator", llm_call_generator)
optimizer_builder.add_node("llm_call_evaluator", llm_call_evaluator)

# Add edges to connect nodes
optimizer_builder.add_edge(START, "llm_call_generator")
optimizer_builder.add_edge("llm_call_generator", "llm_call_evaluator")
optimizer_builder.add_conditional_edges(
    "llm_call_evaluator",
    route_joke,
    {  # Name returned by route_joke : Name of next node to visit
        "Accepted": END,
        "Rejected + Feedback": "llm_call_generator",
    },
)

# Compile the workflow
optimizer_workflow = optimizer_builder.compile()

# Show the workflow
display(Image(optimizer_workflow.get_graph().draw_mermaid_png()))

# Invoke
state = optimizer_workflow.invoke({"topic": "Cats"})
print(state["joke"])
# Schema for structured output to use in evaluation
class Feedback(BaseModel):
    grade: Literal["funny", "not funny"] = Field(
        description="Decide if the joke is funny or not.",
    )
    feedback: str = Field(
        description="If the joke is not funny, provide feedback on how to improve it.",
    )


# Augment the LLM with schema for structured output
evaluator = llm.with_structured_output(Feedback)


# Nodes
@task
def llm_call_generator(topic: str, feedback: Feedback):
    """LLM generates a joke"""
    if feedback:
        msg = llm.invoke(
            f"Write a joke about {topic} but take into account the feedback: {feedback}"
        )
    else:
        msg = llm.invoke(f"Write a joke about {topic}")
    return msg.content


@task
def llm_call_evaluator(joke: str):
    """LLM evaluates the joke"""
    feedback = evaluator.invoke(f"Grade the joke {joke}")
    return feedback


@entrypoint()
def optimizer_workflow(topic: str):
    feedback = None
    while True:
        joke = llm_call_generator(topic, feedback).result()
        feedback = llm_call_evaluator(joke).result()
        if feedback.grade == "funny":
            break

    return joke

# Invoke
stream = optimizer_workflow.stream_events("Cats", version="v3")
for snapshot in stream.values:
    print(snapshot)
    print("\n")
import { StateGraph, StateSchema, GraphNode, ConditionalEdgeRouter } from "@langchain/langgraph";
import * as z from "zod";

// Graph state
const State = new StateSchema({
  joke: z.string(),
  topic: z.string(),
  feedback: z.string(),
  funnyOrNot: z.string(),
});

// Schema for structured output to use in evaluation
const feedbackSchema = z.object({
  grade: z.enum(["funny", "not funny"]).describe(
    "Decide if the joke is funny or not."
  ),
  feedback: z.string().describe(
    "If the joke is not funny, provide feedback on how to improve it."
  ),
});

// Augment the LLM with schema for structured output
const evaluator = llm.withStructuredOutput(feedbackSchema);

// Nodes
const llmCallGenerator: GraphNode<typeof State> = async (state) => {
  // LLM generates a joke
  let msg;
  if (state.feedback) {
    msg = await llm.invoke(
      `Write a joke about ${state.topic} but take into account the feedback: ${state.feedback}`
    );
  } else {
    msg = await llm.invoke(`Write a joke about ${state.topic}`);
  }
  return { joke: msg.content };
};

const llmCallEvaluator: GraphNode<typeof State> = async (state) => {
  // LLM evaluates the joke
  const grade = await evaluator.invoke(`Grade the joke ${state.joke}`);
  return { funnyOrNot: grade.grade, feedback: grade.feedback };
};

// Conditional edge function to route back to joke generator or end based upon feedback from the evaluator
const routeJoke: ConditionalEdgeRouter<{ InputSchema: typeof State; Nodes: "llmCallGenerator" }> = (state) => {
  // Route back to joke generator or end based upon feedback from the evaluator
  if (state.funnyOrNot === "funny") {
    return "Accepted";
  } else {
    return "Rejected + Feedback";
  }
};

// Build workflow
const optimizerWorkflow = new StateGraph(State)
  .addNode("llmCallGenerator", llmCallGenerator)
  .addNode("llmCallEvaluator", llmCallEvaluator)
  .addEdge("__start__", "llmCallGenerator")
  .addEdge("llmCallGenerator", "llmCallEvaluator")
  .addConditionalEdges(
    "llmCallEvaluator",
    routeJoke,
    {
      // Name returned by routeJoke : Name of next node to visit
      "Accepted": "__end__",
      "Rejected + Feedback": "llmCallGenerator",
    }
  )
  .compile();

// Invoke
const state = await optimizerWorkflow.invoke({ topic: "Cats" });
console.log(state.joke);
import * as z from "zod";
import { task, entrypoint } from "@langchain/langgraph";

// Schema for structured output to use in evaluation
const feedbackSchema = z.object({
  grade: z.enum(["funny", "not funny"]).describe(
    "Decide if the joke is funny or not."
  ),
  feedback: z.string().describe(
    "If the joke is not funny, provide feedback on how to improve it."
  ),
});

// Augment the LLM with schema for structured output
const evaluator = llm.withStructuredOutput(feedbackSchema);

// Tasks
const llmCallGenerator = task("jokeGenerator", async (params: {
  topic: string;
  feedback?: z.infer<typeof feedbackSchema>;
}) => {
  // LLM generates a joke
  const msg = params.feedback
    ? await llm.invoke(
        `Write a joke about ${params.topic} but take into account the feedback: ${params.feedback.feedback}`
      )
    : await llm.invoke(`Write a joke about ${params.topic}`);
  return msg.content;
});

const llmCallEvaluator = task("jokeEvaluator", async (joke: string) => {
  // LLM evaluates the joke
  return evaluator.invoke(`Grade the joke ${joke}`);
});

// Build workflow
const workflow = entrypoint(
  "optimizerWorkflow",
  async (topic: string) => {
    let feedback: z.infer<typeof feedbackSchema> | undefined;
    let joke: string;

    while (true) {
      joke = await llmCallGenerator({ topic, feedback });
      feedback = await llmCallEvaluator(joke);

      if (feedback.grade === "funny") {
        break;
      }
    }

    return joke;
  }
);

// Invoke
const stream = await workflow.streamEvents("Cats", { version: "v3" });
for await (const snapshot of stream.values) {
  console.log(snapshot);
  console.log("\n");
}
智能体
智能体通常通过工具实现,以LLM为核心执行操作。它们运行在持续反馈循环中,适用于问题与解决方案不可预知场景。智能体比工作流更具自主性,可自主选择工具及问题解决策略。您仍可定义工具集和行为规范。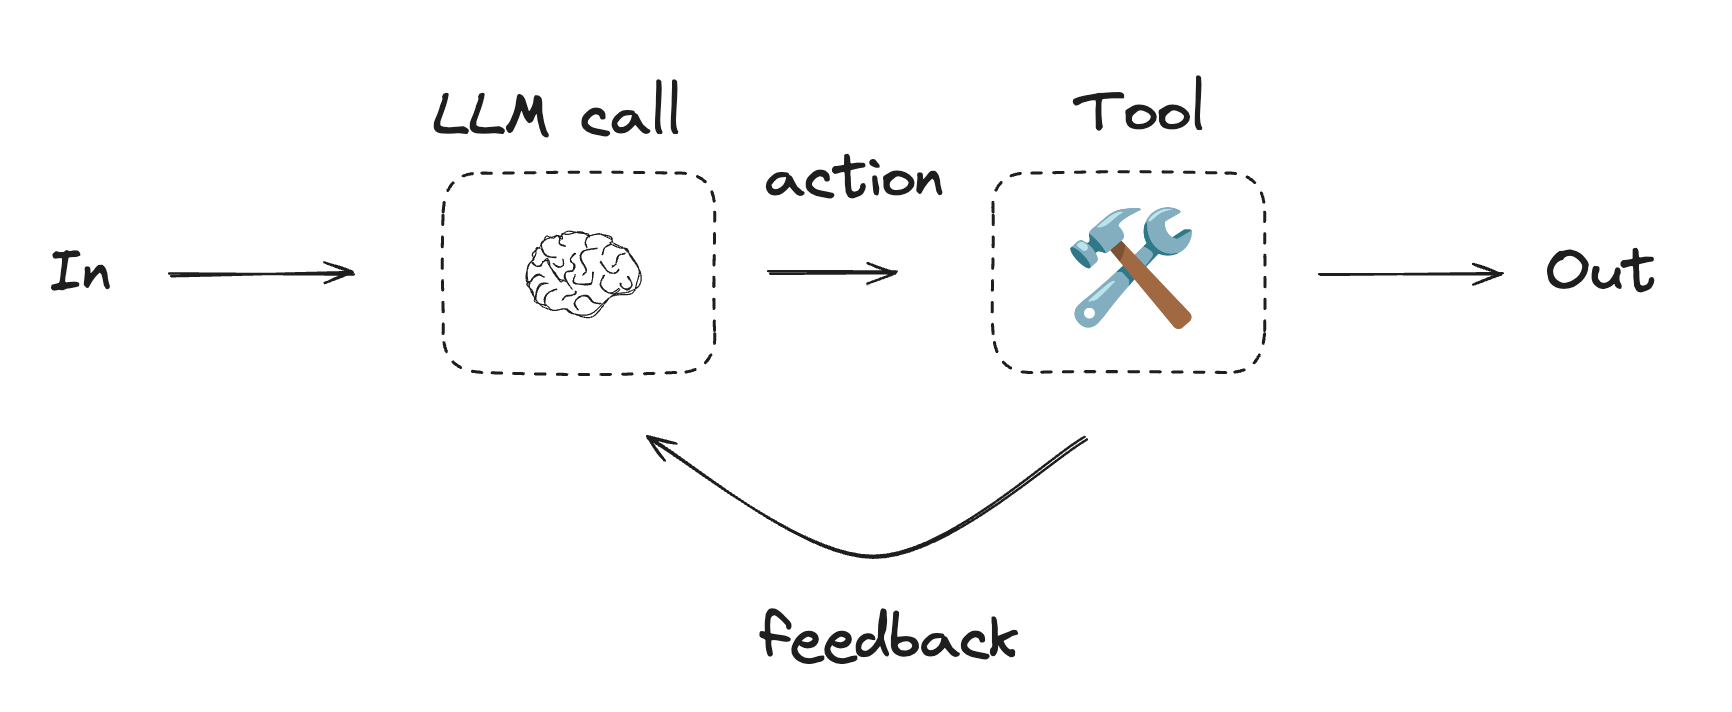
Using tools
from langchain.tools import tool


# Define tools
@tool
def multiply(a: int, b: int) -> int:
    """Multiply `a` and `b`.

    Args:
        a: First int
        b: Second int
    """
    return a * b


@tool
def add(a: int, b: int) -> int:
    """Adds `a` and `b`.

    Args:
        a: First int
        b: Second int
    """
    return a + b


@tool
def divide(a: int, b: int) -> float:
    """Divide `a` and `b`.

    Args:
        a: First int
        b: Second int
    """
    return a / b


# Augment the LLM with tools
tools = [add, multiply, divide]
tools_by_name = {tool.name: tool for tool in tools}
llm_with_tools = llm.bind_tools(tools)
from langgraph.graph import MessagesState
from langchain.messages import SystemMessage, HumanMessage, ToolMessage


# Nodes
def llm_call(state: MessagesState):
    """LLM decides whether to call a tool or not"""

    return {
        "messages": [
            llm_with_tools.invoke(
                [
                    SystemMessage(
                        content="You are a helpful assistant tasked with performing arithmetic on a set of inputs."
                    )
                ]
                + state["messages"]
            )
        ]
    }


def tool_node(state: MessagesState):
    """Performs the tool call"""

    result = []
    for tool_call in state["messages"][-1].tool_calls:
        tool = tools_by_name[tool_call["name"]]
        observation = tool.invoke(tool_call["args"])
        result.append(ToolMessage(content=observation, tool_call_id=tool_call["id"]))
    return {"messages": result}


# Conditional edge function to route to the tool node or end based upon whether the LLM made a tool call
def should_continue(state: MessagesState) -> Literal["tool_node", END]:
    """Decide if we should continue the loop or stop based upon whether the LLM made a tool call"""

    messages = state["messages"]
    last_message = messages[-1]

    # If the LLM makes a tool call, then perform an action
    if last_message.tool_calls:
        return "tool_node"

    # Otherwise, we stop (reply to the user)
    return END


# Build workflow
agent_builder = StateGraph(MessagesState)

# Add nodes
agent_builder.add_node("llm_call", llm_call)
agent_builder.add_node("tool_node", tool_node)

# Add edges to connect nodes
agent_builder.add_edge(START, "llm_call")
agent_builder.add_conditional_edges(
    "llm_call",
    should_continue,
    ["tool_node", END]
)
agent_builder.add_edge("tool_node", "llm_call")

# Compile the agent
agent = agent_builder.compile()

# Show the agent
display(Image(agent.get_graph(xray=True).draw_mermaid_png()))

# Invoke
messages = [HumanMessage(content="Add 3 and 4.")]
messages = agent.invoke({"messages": messages})
for m in messages["messages"]:
    m.pretty_print()
from langgraph.graph import add_messages
from langchain.messages import (
    SystemMessage,
    HumanMessage,
    ToolCall,
)
from langchain_core.messages import BaseMessage


@task
def call_llm(messages: list[BaseMessage]):
    """LLM decides whether to call a tool or not"""
    return llm_with_tools.invoke(
        [
            SystemMessage(
                content="You are a helpful assistant tasked with performing arithmetic on a set of inputs."
            )
        ]
        + messages
    )


@task
def call_tool(tool_call: ToolCall):
    """Performs the tool call"""
    tool = tools_by_name[tool_call["name"]]
    return tool.invoke(tool_call)


@entrypoint()
def agent(messages: list[BaseMessage]):
    llm_response = call_llm(messages).result()

    while True:
        if not llm_response.tool_calls:
            break

        # Execute tools
        tool_result_futures = [
            call_tool(tool_call) for tool_call in llm_response.tool_calls
        ]
        tool_results = [fut.result() for fut in tool_result_futures]
        messages = add_messages(messages, [llm_response, *tool_results])
        llm_response = call_llm(messages).result()

    messages = add_messages(messages, llm_response)
    return messages

# Invoke
messages = [HumanMessage(content="Add 3 and 4.")]
stream = agent.stream_events(messages, version="v3")
for snapshot in stream.values:
    print(snapshot)
    print("\n")
Using tools
import { tool } from "@langchain/core/tools";
import * as z from "zod";

// Define tools
const multiply = tool(
  ({ a, b }) => {
    return a * b;
  },
  {
    name: "multiply",
    description: "Multiply two numbers together",
    schema: z.object({
      a: z.number().describe("first number"),
      b: z.number().describe("second number"),
    }),
  }
);

const add = tool(
  ({ a, b }) => {
    return a + b;
  },
  {
    name: "add",
    description: "Add two numbers together",
    schema: z.object({
      a: z.number().describe("first number"),
      b: z.number().describe("second number"),
    }),
  }
);

const divide = tool(
  ({ a, b }) => {
    return a / b;
  },
  {
    name: "divide",
    description: "Divide two numbers",
    schema: z.object({
      a: z.number().describe("first number"),
      b: z.number().describe("second number"),
    }),
  }
);

// Augment the LLM with tools
const tools = [add, multiply, divide];
const toolsByName = Object.fromEntries(tools.map((tool) => [tool.name, tool]));
const llmWithTools = llm.bindTools(tools);
import { StateGraph, StateSchema, MessagesValue, GraphNode, ConditionalEdgeRouter } from "@langchain/langgraph";
import { ToolNode } from "@langchain/langgraph/prebuilt";
import {
  SystemMessage,
  ToolMessage
} from "@langchain/core/messages";

// Graph state
const State = new StateSchema({
  messages: MessagesValue,
});

// Nodes
const llmCall: GraphNode<typeof State> = async (state) => {
  // LLM decides whether to call a tool or not
  const result = await llmWithTools.invoke([
    {
      role: "system",
      content: "You are a helpful assistant tasked with performing arithmetic on a set of inputs."
    },
    ...state.messages
  ]);

  return {
    messages: [result]
  };
};

const toolNode = new ToolNode(tools);

// Conditional edge function to route to the tool node or end
const shouldContinue: ConditionalEdgeRouter<{ InputSchema: typeof State; Nodes: "toolNode" }> = (state) => {
  const messages = state.messages;
  const lastMessage = messages.at(-1);

  // If the LLM makes a tool call, then perform an action
  if (lastMessage?.tool_calls?.length) {
    return "toolNode";
  }
  // Otherwise, we stop (reply to the user)
  return "__end__";
};

// Build workflow
const agentBuilder = new StateGraph(State)
  .addNode("llmCall", llmCall)
  .addNode("toolNode", toolNode)
  // Add edges to connect nodes
  .addEdge("__start__", "llmCall")
  .addConditionalEdges(
    "llmCall",
    shouldContinue,
    ["toolNode", "__end__"]
  )
  .addEdge("toolNode", "llmCall")
  .compile();

// Invoke
const messages = [{
  role: "user",
  content: "Add 3 and 4."
}];
const result = await agentBuilder.invoke({ messages });
console.log(result.messages);
import { task, entrypoint, addMessages } from "@langchain/langgraph";
import { BaseMessageLike, ToolCall } from "@langchain/core/messages";

const callLlm = task("llmCall", async (messages: BaseMessageLike[]) => {
  // LLM decides whether to call a tool or not
  return llmWithTools.invoke([
    {
      role: "system",
      content: "You are a helpful assistant tasked with performing arithmetic on a set of inputs."
    },
    ...messages
  ]);
});

const callTool = task("toolCall", async (toolCall: ToolCall) => {
  // Performs the tool call
  const tool = toolsByName[toolCall.name];
  return tool.invoke(toolCall.args);
});

const agent = entrypoint(
  "agent",
  async (messages) => {
    let llmResponse = await callLlm(messages);

    while (true) {
      if (!llmResponse.tool_calls?.length) {
        break;
      }

      // Execute tools
      const toolResults = await Promise.all(
        llmResponse.tool_calls.map((toolCall) => callTool(toolCall))
      );

      messages = addMessages(messages, [llmResponse, ...toolResults]);
      llmResponse = await callLlm(messages);
    }

    messages = addMessages(messages, [llmResponse]);
    return messages;
  }
);

// Invoke
const messages = [{
  role: "user",
  content: "Add 3 and 4."
}];

const stream = await agent.streamEvents([messages], { version: "v3" });
for await (const snapshot of stream.values) {
  console.log(snapshot);
}
工具节点
@[ToolNode] 是 LangGraph 工作流中预构建的节点,用于执行工具。它自动处理并行工具执行、错误处理和状态注入。
当需要精确控制图执行工具的方式时,使用 @[ToolNode]。这是许多 LangGraph 智能体模式中工具执行的基础组件。
:::python
from langchain.tools import tool
from langgraph.prebuilt import ToolNode
from langgraph.graph import MessagesState, StateGraph

@tool
def search(query: str) -> str:
    """Search for information."""
    return f"Results for: {query}"

@tool
def calculator(expression: str) -> str:
    """Evaluate a math expression."""
    return str(eval(expression))

builder = StateGraph(MessagesState)
builder.add_node("tools", ToolNode([search, calculator]))
# ... add other nodes and edges
graph = builder.compile()
import { ToolNode } from "@langchain/langgraph/prebuilt";
import { tool } from "@langchain/core/tools";
import * as z from "zod";

const search = tool(
  ({ query }) => `Results for: ${query}`,
  {
    name: "search",
    description: "Search for information.",
    schema: z.object({ query: z.string() }),
  }
);

const calculator = tool(
  ({ expression }) => String(eval(expression)),
  {
    name: "calculator",
    description: "Evaluate a math expression.",
    schema: z.object({ expression: z.string() }),
  }
);

const toolNode = new ToolNode([search, calculator]);
从工具访问图状态和上下文
由ToolNode 执行的工具会以模型生成的参数作为第一个参数接收。要读取未由模型生成的图侧数据,可以使用以下任一选项:
- 在 Python 中,从注入的 @[
ToolRuntime] 参数中读取状态和运行时上下文。 - 在 JavaScript 中,从工具的第二个参数(类型为 @[
ToolRuntime])中读取状态和运行时上下文。
工具只能访问被传递给
ToolNode 的状态值。当 ToolNode 直接作为 StateGraph 节点添加时,该输入即为当前图状态。如果从其他节点手动调用 ToolNode,当工具需要自定义状态字段时,请传递完整状态。例如 tool_node.invoke(state) 或 toolNode.invoke(state, config) 会暴露完整状态,而仅传递 {"messages": state["messages"]} 或 { messages: state.messages } 只会暴露 messages。from dataclasses import dataclass
from langchain.messages import AIMessage
from langchain.tools import ToolRuntime, tool
from langgraph.graph import MessagesState, START, StateGraph
from langgraph.prebuilt import ToolNode
class State(MessagesState):
user_id: str
@dataclass
class Context:
organization_id: str
@tool
def get_user_info(runtime: ToolRuntime[Context, State]) -> str:
"""Look up user information."""
# Read the current graph state passed to the ToolNode.
user_id = runtime.state["user_id"]
# Read explicit per-run values that are not part of graph state.
organization_id = runtime.context.organization_id
return f"User {user_id} in organization {organization_id}"
builder = StateGraph(State, context_schema=Context)
builder.add_node("tools", ToolNode([get_user_info]))
builder.add_edge(START, "tools")
graph = builder.compile()
result = graph.invoke(
{
"messages": [
AIMessage(
content="",
tool_calls=[
{
"name": "get_user_info",
"args": {},
"id": "call_user_info",
}
],
)
],
"user_id": "user_123",
},
context=Context(organization_id="org_456"),
)
View example trace
为此示例打开一个公开的 LangSmith 运行。
import { AIMessage } from "@langchain/core/messages";
import { tool, type ToolRuntime } from "@langchain/core/tools";
import {
  MessagesValue,
  START,
  StateGraph,
  StateSchema,
} from "@langchain/langgraph";
import { ToolNode } from "@langchain/langgraph/prebuilt";
import * as z from "zod";

const State = new StateSchema({
  messages: MessagesValue,
  userId: z.string(),
});

const ContextSchema = z.object({
  organizationId: z.string(),
});

const getUserInfo = tool(
  async (
    _input,
    runtime: ToolRuntime<typeof State.Type, typeof ContextSchema>,
  ) => {
    // Read the current graph state passed to the ToolNode.
    const userIdFromState = runtime.state?.userId;
    const userIdFromTaskInput = (
      runtime.configurable as {
        __pregel_scratchpad?: { currentTaskInput?: { userId?: string } };
      }
    ).__pregel_scratchpad?.currentTaskInput?.userId;
    const userId = userIdFromState ?? userIdFromTaskInput;
    if (!userId) {
      throw new Error("Missing userId in ToolRuntime state.");
    }

    // Use runtime context for explicit per-run values that are not part
    // of graph state.
    const organizationId = runtime.context.organizationId;

    return `User ${userId} in organization ${organizationId}`;
  },
  {
    name: "get_user_info",
    description: "Look up user information.",
    schema: z.object({}),
  },
);

const graph = new StateGraph(State, ContextSchema)
  .addNode("tools", new ToolNode([getUserInfo]))
  .addEdge(START, "tools")
  .compile();

const result = await graph.invoke(
  {
    messages: [
      new AIMessage({
        content: "",
        tool_calls: [{ name: "get_user_info", args: {}, id: "call_user_info" }],
      }),
    ],
    userId: "user_123",
  },
  { context: { organizationId: "org_456" } },
);
View example trace
为此示例打开一个公开的 LangSmith 运行。
官方原文:src/oss/langgraph/workflows-agents.mdx · 非官方翻译,译文由 AI 生成,以英文原文为准。