构建 SQL 数据库的 Q&A 系统需要执行模型生成的 SQL 查询。这样做存在固有的风险。确保您的数据库连接权限始终尽可能狭窄地限制在智能体的需求范围内。这将减轻(尽管不能完全消除)构建模型驱动系统的风险。
概念
我们将涵盖以下概念:设置
安装
:::pythonpip install langchain langgraph
npm i langchain @langchain/core @langchain/langgraph @langchain/openai sqlite3 zod
yarn add langchain @langchain/core @langchain/langgraph @langchain/openai sqlite3 zod
pnpm add langchain @langchain/core @langchain/langgraph @langchain/openai sqlite3 zod
LangSmith
设置 LangSmith 以检查链或智能体内部的运行情况。然后设置以下环境变量:export LANGSMITH_TRACING="true"
export LANGSMITH_API_KEY="..."
1. 选择 LLM
选择一个支持 工具调用 的模型: :::python- OpenAI
- Anthropic
- Azure
- Google Gemini
- AWS Bedrock
- HuggingFace
- OpenRouter
👉 请阅读 OpenAI 对话模型集成文档
pip install -U "langchain[openai]"
uv add "langchain[openai]"
import os
from langchain.chat_models import init_chat_model

os.environ["OPENAI_API_KEY"] = "sk-..."

model = init_chat_model("gpt-5.5")
import os
from langchain_openai import ChatOpenAI

os.environ["OPENAI_API_KEY"] = "sk-..."

model = ChatOpenAI(model="gpt-5.5")
👉 请阅读 Anthropic 对话模型集成文档
pip install -U "langchain[anthropic]"
uv add "langchain[anthropic]"
import os
from langchain.chat_models import init_chat_model

os.environ["ANTHROPIC_API_KEY"] = "sk-..."

model = init_chat_model("claude-sonnet-4-6")
import os
from langchain_anthropic import ChatAnthropic

os.environ["ANTHROPIC_API_KEY"] = "sk-..."

model = ChatAnthropic(model="claude-sonnet-4-6")
👉 请阅读 Azure 对话模型集成文档
pip install -U "langchain[openai]"
uv add "langchain[openai]"
import os
from langchain.chat_models import init_chat_model

os.environ["AZURE_OPENAI_API_KEY"] = "..."
os.environ["AZURE_OPENAI_ENDPOINT"] = "..."
os.environ["OPENAI_API_VERSION"] = "2025-03-01-preview"

model = init_chat_model(
    "azure_openai:gpt-5.5",
    azure_deployment=os.environ["AZURE_OPENAI_DEPLOYMENT_NAME"],
)
import os
from langchain_openai import AzureChatOpenAI

os.environ["AZURE_OPENAI_API_KEY"] = "..."
os.environ["AZURE_OPENAI_ENDPOINT"] = "..."
os.environ["OPENAI_API_VERSION"] = "2025-03-01-preview"

model = AzureChatOpenAI(
    model="gpt-5.5",
    azure_deployment=os.environ["AZURE_OPENAI_DEPLOYMENT_NAME"]
)
👉 请阅读 Google GenAI 对话模型集成文档
pip install -U "langchain[google-genai]"
uv add "langchain[google-genai]"
import os
from langchain.chat_models import init_chat_model

os.environ["GOOGLE_API_KEY"] = "..."

model = init_chat_model("google_genai:gemini-3.7-flash")
import os
from langchain_google_genai import ChatGoogleGenerativeAI

os.environ["GOOGLE_API_KEY"] = "..."

model = ChatGoogleGenerativeAI(model="gemini-3.7-flash")
👉 请阅读 AWS Bedrock 对话模型集成文档
pip install -U "langchain[aws]"
uv add "langchain[aws]"
from langchain.chat_models import init_chat_model

# Follow the steps here to configure your credentials:
# https://docs.aws.amazon.com/bedrock/latest/userguide/getting-started.html

model = init_chat_model(
    "us.anthropic.claude-sonnet-4-6",
    model_provider="bedrock_converse",
)
from langchain_aws import ChatBedrock

model = ChatBedrock(model="us.anthropic.claude-sonnet-4-6")
👉 请阅读 HuggingFace 对话模型集成文档
pip install -U "langchain[huggingface]"
uv add "langchain[huggingface]"
import os
from langchain.chat_models import init_chat_model

os.environ["HUGGINGFACEHUB_API_TOKEN"] = "hf_..."

model = init_chat_model(
    "microsoft/Phi-3-mini-4k-instruct",
    model_provider="huggingface",
    temperature=0.7,
    max_tokens=1024,
)
import os
from langchain_huggingface import ChatHuggingFace, HuggingFaceEndpoint

os.environ["HUGGINGFACEHUB_API_TOKEN"] = "hf_..."

llm = HuggingFaceEndpoint(
    repo_id="microsoft/Phi-3-mini-4k-instruct",
    temperature=0.7,
    max_length=1024,
)
model = ChatHuggingFace(llm=llm)
👉 请阅读 OpenRouter 对话模型集成文档
pip install -U "langchain-openrouter"
uv add "langchain-openrouter"
import os
from langchain.chat_models import init_chat_model

os.environ["OPENROUTER_API_KEY"] = "sk-..."

model = init_chat_model(
    "auto",
    model_provider="openrouter",
)
import os
from langchain_openrouter import ChatOpenRouter

os.environ["OPENROUTER_API_KEY"] = "sk-..."

model = ChatOpenRouter(model="auto")
- OpenAI
- Anthropic
- Azure
- Google Gemini
- Bedrock Converse
👉 Read the OpenAI 对话模型集成文档
npm install @langchain/openai
pnpm install @langchain/openai
yarn add @langchain/openai
bun add @langchain/openai
import { initChatModel } from "langchain";

process.env.OPENAI_API_KEY = "your-api-key";

const model = await initChatModel("gpt-5.5");
import { ChatOpenAI } from "@langchain/openai";

const model = new ChatOpenAI({
  model: "gpt-5.5",
  apiKey: "your-api-key"
});
👉 Read the Anthropic 对话模型集成文档
npm install @langchain/anthropic
pnpm install @langchain/anthropic
yarn add @langchain/anthropic
pnpm add @langchain/anthropic
import { initChatModel } from "langchain";

process.env.ANTHROPIC_API_KEY = "your-api-key";

const model = await initChatModel("claude-sonnet-4-6");
import { ChatAnthropic } from "@langchain/anthropic";

const model = new ChatAnthropic({
  model: "claude-sonnet-4-6",
  apiKey: "your-api-key"
});
👉 Read the Azure 对话模型集成文档
npm install @langchain/azure
pnpm install @langchain/azure
yarn add @langchain/azure
bun add @langchain/azure
import { initChatModel } from "langchain";

process.env.AZURE_OPENAI_API_KEY = "your-api-key";
process.env.AZURE_OPENAI_ENDPOINT = "your-endpoint";
process.env.OPENAI_API_VERSION = "your-api-version";

const model = await initChatModel("azure_openai:gpt-5.5");
import { AzureChatOpenAI } from "@langchain/openai";

const model = new AzureChatOpenAI({
  model: "gpt-5.5",
  azureOpenAIApiKey: "your-api-key",
  azureOpenAIApiEndpoint: "your-endpoint",
  azureOpenAIApiVersion: "your-api-version"
});
👉 Read the ChatGoogle 对话模型集成文档
npm install @langchain/google
pnpm install @langchain/google
yarn add @langchain/google
bun add @langchain/google
import { initChatModel } from "langchain";

process.env.GOOGLE_API_KEY = "your-api-key";

const model = await initChatModel("google:gemini-3.7-flash");
import { ChatGoogle } from "@langchain/google/node";

const model = new ChatGoogle({
  model: "gemini-3.7-flash",
  apiKey: "your-api-key"
});
👉 Read the AWS Bedrock 对话模型集成文档
npm install @langchain/aws
pnpm install @langchain/aws
yarn add @langchain/aws
bun add @langchain/aws
import { initChatModel } from "langchain";

// Follow the steps here to configure your credentials:
// https://docs.aws.amazon.com/bedrock/latest/userguide/getting-started.html

const model = await initChatModel("bedrock:gpt-5.5");
import { ChatBedrockConverse } from "@langchain/aws";

// Follow the steps here to configure your credentials:
// https://docs.aws.amazon.com/bedrock/latest/userguide/getting-started.html

const model = new ChatBedrockConverse({
  model: "gpt-5.5",
  region: "us-east-2"
});
2. 配置数据库
在本教程中,您将创建一个 SQLite 数据库。SQLite 是一个轻量级数据库,易于设置和使用。我们将加载chinook 数据库,这是一个表示数字媒体商店的示例数据库。
为了方便起见,我们将数据库(Chinook.db)托管在公共 GCS 存储桶上。
:::python
import pathlib
import requests

url = "https://storage.googleapis.com/benchmarks-artifacts/chinook/Chinook.db"
local_path = pathlib.Path("Chinook.db")

if local_path.exists():
    print(f"{local_path} already exists, skipping download.")
else:
    response = requests.get(url, timeout=60)
    if response.status_code == 200:
        local_path.write_bytes(response.content)
        print(f"File downloaded and saved as {local_path}")
    else:
        print(f"Failed to download the file. Status code: {response.status_code}")
sqlite3 模块与数据库交互:
import sqlite3

con = sqlite3.connect("Chinook.db")
cursor = con.cursor()

cursor.execute("SELECT name FROM sqlite_master WHERE type='table';")
tables = [row[0] for row in cursor.fetchall() if not row[0].startswith("sqlite_")]

print("Dialect: sqlite")
print(f"Available tables: {tables}")

cursor.execute("SELECT * FROM Artist LIMIT 5;")
print(f"Sample output: {cursor.fetchall()}")
con.close()
Dialect: sqlite
Available tables: ['Album', 'Artist', 'Customer', 'Employee', 'Genre', 'Invoice', 'InvoiceLine', 'MediaType', 'Playlist', 'PlaylistTrack', 'Track']
Sample output: [(1, 'AC/DC'), (2, 'Accept'), (3, 'Aerosmith'), (4, 'Alanis Morissette'), (5, 'Alice In Chains')]
import fs from "node:fs/promises";
import path from "node:path";

const url =
  "https://storage.googleapis.com/benchmarks-artifacts/chinook/Chinook.db";
const localPath = path.resolve("Chinook.db");

async function resolveDbPath() {
  const exists = await fs
    .access(localPath)
    .then(() => true)
    .catch(() => false);
  if (exists) {
    console.log(`${localPath} already exists, skipping download.`);
    return localPath;
  }
  const resp = await fetch(url);
  if (!resp.ok)
    throw new Error(`Failed to download DB. Status code: ${resp.status}`);
  const buf = Buffer.from(await resp.arrayBuffer());
  await fs.writeFile(localPath, buf);
  console.log(`File downloaded and saved as ${localPath}`);
  return localPath;
}
sqlite3 库与数据库交互:
import sqlite3 from "sqlite3";

const dialect = "sqlite";

async function runQuery(query: string, params: unknown[] = []): Promise<any[]> {
  const dbPath = await resolveDbPath();
  const db = new sqlite3.Database(dbPath);
  return new Promise((resolve, reject) => {
    db.all(query, params, (err, rows) => {
      db.close();
      if (err) reject(err);
      else resolve(rows);
    });
  });
}

const tableRows = await runQuery(
  "SELECT name FROM sqlite_master WHERE type='table' AND name NOT LIKE 'sqlite_%';",
);
const tableNames = tableRows.map((row) => String(row.name));
console.log(`Dialect: ${dialect}`);
console.log(`Available tables: ${tableNames.join(", ")}`);
const sampleResults = await runQuery("SELECT * FROM Artist LIMIT 5;");
console.log(`Sample output: ${JSON.stringify(sampleResults)}`);
Dialect: sqlite
Available tables: Album, Artist, Customer, Employee, Genre, Invoice, InvoiceLine, MediaType, Playlist, PlaylistTrack, Track
Sample output: [{"ArtistId":1,"Name":"AC/DC"},{"ArtistId":2,"Name":"Accept"},{"ArtistId":3,"Name":"Aerosmith"},{"ArtistId":4,"Name":"Alanis Morissette"},{"ArtistId":5,"Name":"Alice In Chains"}]
3. 添加用于数据库交互的工具
以下数据库工具仅用于演示目的,是极简的包装器。它们不打算用于生产环境或保证安全性。在使用模型生成的 SQL 之前,请使用狭窄范围的数据库权限并添加应用程序特定的验证。
@tool 装饰器从 langchain.tools 实现数据库 工具 作为薄包装器:
import sqlite3
from langchain.tools import tool

# Below are minimal tools for demonstration purposes.


@tool
def sql_db_list_tables() -> str:
    """Input is an empty string, output is a comma-separated list of tables in the database."""
    con = sqlite3.connect("Chinook.db")
    try:
        cursor = con.cursor()
        cursor.execute("SELECT name FROM sqlite_master WHERE type='table';")
        tables = [
            row[0]
            for row in cursor.fetchall()
            if not row[0].startswith("sqlite_")
        ]
        return ", ".join(tables)
    finally:
        con.close()


@tool
def sql_db_schema(table_names: str) -> str:
    """Input to this tool is a comma-separated list of tables, output is the schema and sample rows for those tables.
    Be sure that the tables actually exist by calling sql_db_list_tables first!
    Example Input: table1, table2, table3"""
    con = sqlite3.connect("Chinook.db")
    try:
        cursor = con.cursor()
        cursor.execute("SELECT name FROM sqlite_master WHERE type='table';")
        valid_tables = {
            row[0] for row in cursor.fetchall() if not row[0].startswith("sqlite_")
        }
        results = []
        for table in table_names.split(","):
            table = table.strip()
            if table not in valid_tables:
                results.append(
                    f"Error: table_names {{{table!r}}} not found in database"
                )
                continue
            cursor.execute(
                "SELECT sql FROM sqlite_master WHERE type='table' AND name=?;",
                (table,),
            )
            schema_row = cursor.fetchone()
            if schema_row:
                results.append(schema_row[0])
                try:
                    quoted_table = '"' + table.replace('"', '""') + '"'
                    cursor.execute(f"SELECT * FROM {quoted_table} LIMIT 3;")
                    rows = cursor.fetchall()
                    if rows:
                        col_names = [description[0] for description in cursor.description]
                        results.append(
                            f"/*\n3 rows from {table} table:\n"
                            + "\t".join(col_names)
                            + "\n"
                            + "\n".join(
                                "\t".join(str(x) for x in row) for row in rows
                            )
                            + "\n*/"
                        )
                except Exception as e:
                    results.append(f"Error fetching sample rows: {e}")
        return "\n\n".join(results)
    finally:
        con.close()


@tool
def sql_db_query(query: str) -> str:
    """Input to this tool is a detailed and correct SQL query, output is a result from the database.
    If the query is not correct, an error message will be returned.
    If an error is returned, rewrite the query, check the query, and try again.
    If you encounter an issue with Unknown column 'xxxx' in 'field list', use sql_db_schema to query the correct table fields."""
    con = sqlite3.connect("Chinook.db")
    try:
        cursor = con.cursor()
        cursor.execute(query)
        res = cursor.fetchall()
        return str(res)
    except Exception as e:
        return f"Error: {e}"
    finally:
        con.close()


tools = [sql_db_list_tables, sql_db_schema, sql_db_query]

# Use a distinct loop variable so it does not shadow the `tool` decorator,
# which is reused later to wrap the query tool for human review.
for t in tools:
    print(f"{t.name}: {t.description}\n")
sql_db_list_tables: Input is an empty string, output is a comma-separated list of tables in the database.

sql_db_schema: Input to this tool is a comma-separated list of tables, output is the schema and sample rows for those tables.
    Be sure that the tables actually exist by calling sql_db_list_tables first!
    Example Input: table1, table2, table3

sql_db_query: Input to this tool is a detailed and correct SQL query, output is a result from the database.
    If the query is not correct, an error message will be returned.
    If an error is returned, rewrite the query, check the query, and try again.
    If you encounter an issue with Unknown column 'xxxx' in 'field list', use sql_db_schema to query the correct table fields.
import { tool } from "langchain";
import * as z from "zod";

async function getTableNames() {
  const rows = await runQuery(
    "SELECT name FROM sqlite_master WHERE type='table' AND name NOT LIKE 'sqlite_%';",
  );
  return rows.map((row) => String(row.name));
}

function quoteSqliteIdentifier(identifier: string) {
  return `"${identifier.replaceAll('"', '""')}"`;
}

const listTablesTool = tool(
  async () => {
    const tableNames = await getTableNames();
    return tableNames.join(", ");
  },
  {
    name: "sql_db_list_tables",
    description:
      "Input is an empty string, output is a comma-separated list of tables in the database.",
    schema: z.object({}),
  },
);

const getSchemaTool = tool(
  async ({ table_names }) => {
    const validTables = new Set(await getTableNames());
    const results: string[] = [];
    for (const table of table_names.split(",").map((t) => t.trim())) {
      if (!validTables.has(table)) {
        results.push(`Error: table_names {'${table}'} not found in database`);
        continue;
      }
      const schemaRows = await runQuery(
        "SELECT sql FROM sqlite_master WHERE type='table' AND name=?;",
        [table],
      );
      const schema = schemaRows[0]?.sql;
      if (schema) {
        results.push(String(schema));
        try {
          const rows = await runQuery(
            `SELECT * FROM ${quoteSqliteIdentifier(table)} LIMIT 3;`,
          );
          if (rows.length > 0) {
            const colNames = Object.keys(rows[0]);
            results.push(
              `/*\n3 rows from ${table} table:\n${colNames.join("\t")}\n` +
                rows
                  .map((row) =>
                    colNames.map((col) => String(row[col])).join("\t"),
                  )
                  .join("\n") +
                "\n*/",
            );
          }
        } catch (e) {
          results.push(`Error fetching sample rows: ${e}`);
        }
      }
    }
    return results.join("\n\n");
  },
  {
    name: "sql_db_schema",
    description:
      "Input to this tool is a comma-separated list of tables, output is the schema and sample rows for those tables. Be sure that the tables actually exist by calling sql_db_list_tables first! Example Input: table1, table2, table3",
    schema: z.object({
      table_names: z.string().describe("Comma-separated list of table names"),
    }),
  },
);

const queryTool = tool(
  async ({ query }) => {
    try {
      const result = await runQuery(query);
      return JSON.stringify(result);
    } catch (error) {
      return `Error: ${error instanceof Error ? error.message : String(error)}`;
    }
  },
  {
    name: "sql_db_query",
    description:
      "Input to this tool is a detailed and correct SQL query, output is a result from the database. If the query is not correct, an error message will be returned. If an error is returned, rewrite the query, check the query, and try again.",
    schema: z.object({
      query: z.string().describe("SQL query to execute"),
    }),
  },
);

const tools = [listTablesTool, getSchemaTool, queryTool];

for (const toolItem of tools) {
  console.log(`${toolItem.name}: ${toolItem.description}\n`);
}
sql_db_list_tables: Input is an empty string, output is a comma-separated list of tables in the database.

sql_db_schema: Input to this tool is a comma-separated list of tables, output is the schema and sample rows for those tables. Be sure that the tables actually exist by calling sql_db_list_tables first! Example Input: table1, table2, table3

sql_db_query: Input to this tool is a detailed and correct SQL query, output is a result from the database. If the query is not correct, an error message will be returned. If an error is returned, rewrite the query, check the query, and try again.
4. 定义应用步骤
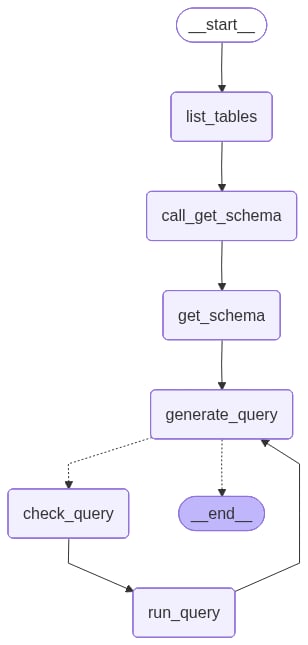
我们为以下步骤构建专用节点:- 列出数据库表
- 调用 “获取架构” 工具
- 生成查询
- 检查查询
from typing import Literal

from langchain.messages import AIMessage
from langchain_core.runnables import RunnableConfig
from langgraph.graph import END, START, MessagesState, StateGraph
from langgraph.prebuilt import ToolNode

get_schema_tool = next(tool for tool in tools if tool.name == "sql_db_schema")
get_schema_node = ToolNode([get_schema_tool], name="get_schema")

run_query_tool = next(tool for tool in tools if tool.name == "sql_db_query")
run_query_node = ToolNode([run_query_tool], name="run_query")


# Example: create a predetermined tool call
def list_tables(state: MessagesState):
    tool_call = {
        "name": "sql_db_list_tables",
        "args": {},
        "id": "abc123",
        "type": "tool_call",
    }
    tool_call_message = AIMessage(content="", tool_calls=[tool_call])

    list_tables_tool = next(tool for tool in tools if tool.name == "sql_db_list_tables")
    tool_message = list_tables_tool.invoke(tool_call)
    response = AIMessage(f"Available tables: {tool_message.content}")

    return {"messages": [tool_call_message, tool_message, response]}


# Example: force a model to create a tool call
def call_get_schema(state: MessagesState):
    # Note that LangChain enforces that all models accept `tool_choice="any"`
    # as well as `tool_choice=<string name of tool>`.
    llm_with_tools = model.bind_tools([get_schema_tool], tool_choice="any")
    response = llm_with_tools.invoke(state["messages"])

    return {"messages": [response]}


generate_query_system_prompt = """
You are an agent designed to interact with a SQL database.
Given an input question, create a syntactically correct {dialect} query to run,
then look at the results of the query and return the answer. Unless the user
specifies a specific number of examples they wish to obtain, always limit your
query to at most {top_k} results.

You can order the results by a relevant column to return the most interesting
examples in the database. Never query for all the columns from a specific table,
only ask for the relevant columns given the question.

DO NOT make any DML statements (INSERT, UPDATE, DELETE, DROP etc.) to the database.
""".format(
    dialect="sqlite",
    top_k=5,
)


def generate_query(state: MessagesState):
    system_message = {
        "role": "system",
        "content": generate_query_system_prompt,
    }
    # We do not force a tool call here, to allow the model to
    # respond naturally when it obtains the solution.
    llm_with_tools = model.bind_tools([run_query_tool])
    response = llm_with_tools.invoke([system_message] + state["messages"])

    return {"messages": [response]}


check_query_system_prompt = """
You are a SQL expert with a strong attention to detail.
Double check the {dialect} query for common mistakes, including:
- Using NOT IN with NULL values
- Using UNION when UNION ALL should have been used
- Using BETWEEN for exclusive ranges
- Data type mismatch in predicates
- Properly quoting identifiers
- Using the correct number of arguments for functions
- Casting to the correct data type
- Using the proper columns for joins

If there are any of the above mistakes, rewrite the query. If there are no mistakes,
just reproduce the original query.

You will call the appropriate tool to execute the query after running this check.
""".format(dialect="sqlite")


def check_query(state: MessagesState):
    system_message = {
        "role": "system",
        "content": check_query_system_prompt,
    }

    # Generate an artificial user message to check
    tool_call = state["messages"][-1].tool_calls[0]
    user_message = {"role": "user", "content": tool_call["args"]["query"]}
    llm_with_tools = model.bind_tools([run_query_tool], tool_choice="any")
    response = llm_with_tools.invoke([system_message, user_message])
    response.id = state["messages"][-1].id

    return {"messages": [response]}
import {
  AIMessage,
  HumanMessage,
  SystemMessage,
  ToolMessage,
} from "@langchain/core/messages";
import { ToolNode } from "@langchain/langgraph/prebuilt";
import {
  END,
  GraphNode,
  MessagesValue,
  START,
  StateGraph,
  StateSchema,
} from "@langchain/langgraph";

// Create tool nodes for schema and query execution
const getSchemaNode = new ToolNode([getSchemaTool]);
const runQueryNode = new ToolNode([queryTool]);

// Define state schema
const MessagesState = new StateSchema({
  messages: MessagesValue,
});

// Example: create a predetermined tool call
const listTables: GraphNode<typeof MessagesState> = async (state) => {
  const toolCall = {
    name: "sql_db_list_tables",
    args: {},
    id: "abc123",
    type: "tool_call" as const,
  };
  const toolCallMessage = new AIMessage({
    content: "",
    tool_calls: [toolCall],
  });

  const toolMessage = await listTablesTool.invoke({});
  const response = new AIMessage(`Available tables: ${toolMessage}`);

  return {
    messages: [
      toolCallMessage,
      new ToolMessage({ content: toolMessage, tool_call_id: "abc123" }),
      response,
    ],
  };
};

// Example: force a model to create a tool call
const callGetSchema: GraphNode<typeof MessagesState> = async (state) => {
  const llmWithTools = model!.bindTools([getSchemaTool], {
    tool_choice: "any",
  });
  const response = await llmWithTools.invoke(state.messages);

  return { messages: [response] };
};

const topK = 5;

const generateQuerySystemPrompt = `
You are an agent designed to interact with a SQL database.
Given an input question, create a syntactically correct ${dialect}
query to run, then look at the results of the query and return the answer. Unless
the user specifies a specific number of examples they wish to obtain, always limit
your query to at most ${topK} results.

You can order the results by a relevant column to return the most interesting
examples in the database. Never query for all the columns from a specific table,
only ask for the relevant columns given the question.

DO NOT make any DML statements (INSERT, UPDATE, DELETE, DROP etc.) to the database.
`;

const generateQuery: GraphNode<typeof MessagesState> = async (state) => {
  const systemMessage = new SystemMessage(generateQuerySystemPrompt);
  // We do not force a tool call here, to allow the model to
  // respond naturally when it obtains the solution.
  const llmWithTools = model!.bindTools([queryTool]);
  const response = await llmWithTools.invoke([
    systemMessage,
    ...state.messages,
  ]);

  return { messages: [response] };
};

const checkQuerySystemPrompt = `
You are a SQL expert with a strong attention to detail.
Double check the ${dialect} query for common mistakes, including:
- Using NOT IN with NULL values
- Using UNION when UNION ALL should have been used
- Using BETWEEN for exclusive ranges
- Data type mismatch in predicates
- Properly quoting identifiers
- Using the correct number of arguments for functions
- Casting to the correct data type
- Using the proper columns for joins

If there are any of the above mistakes, rewrite the query. If there are no mistakes,
just reproduce the original query.

You will call the appropriate tool to execute the query after running this check.
`;

const checkQuery: GraphNode<typeof MessagesState> = async (state) => {
  const systemMessage = new SystemMessage(checkQuerySystemPrompt);

  // Generate an artificial user message to check
  const lastMessage = state.messages[state.messages.length - 1];
  if (!AIMessage.isInstance(lastMessage) || !lastMessage.tool_calls?.length) {
    throw new Error("No tool calls found in the last message");
  }
  const toolCall = lastMessage.tool_calls[0];
  const userMessage = new HumanMessage(toolCall.args.query);
  const llmWithTools = model!.bindTools([queryTool], {
    tool_choice: "any",
  });
  const response = await llmWithTools.invoke([systemMessage, userMessage]);
  // Preserve the original message ID
  response.id = lastMessage.id;

  return { messages: [response] };
};
5. 实现智能体
现在我们可以使用 Graph API 将这些步骤组装成一个工作流。我们在查询生成步骤定义了一个 条件边,如果生成了查询则路由到查询检查器,如果没有工具调用则结束,这样 LLM 就能对查询做出响应。 :::pythondef should_continue(state: MessagesState) -> Literal[END, "check_query"]:
messages = state["messages"]
last_message = messages[-1]
if not last_message.tool_calls:
return END
else:
return "check_query"
builder = StateGraph(MessagesState)
builder.add_node(list_tables)
builder.add_node(call_get_schema)
builder.add_node(get_schema_node, "get_schema")
builder.add_node(generate_query)
builder.add_node(check_query)
builder.add_node(run_query_node, "run_query")
builder.add_edge(START, "list_tables")
builder.add_edge("list_tables", "call_get_schema")
builder.add_edge("call_get_schema", "get_schema")
builder.add_edge("get_schema", "generate_query")
builder.add_conditional_edges(
"generate_query",
should_continue,
)
builder.add_edge("check_query", "run_query")
builder.add_edge("run_query", "generate_query")
agent = builder.compile()
import pathlib

pathlib.Path("graph.png").write_bytes(agent.get_graph().draw_mermaid_png())
import { ConditionalEdgeRouter } from "@langchain/langgraph";

const shouldContinue: ConditionalEdgeRouter<{ InputSchema: typeof MessagesState; Nodes: "check_query" }> = (state) => {
  const messages = state.messages;
  const lastMessage = messages[messages.length - 1];
  if (!AIMessage.isInstance(lastMessage) || !lastMessage.tool_calls?.length) {
    return END;
  } else {
    return "check_query";
  }
};

const builder = new StateGraph(MessagesState)
  .addNode("list_tables", listTables)
  .addNode("call_get_schema", callGetSchema)
  .addNode("get_schema", getSchemaNode)
  .addNode("generate_query", generateQuery)
  .addNode("check_query", checkQuery)
  .addNode("run_query", runQueryNode)
  .addEdge(START, "list_tables")
  .addEdge("list_tables", "call_get_schema")
  .addEdge("call_get_schema", "get_schema")
  .addEdge("get_schema", "generate_query")
  .addConditionalEdges("generate_query", shouldContinue)
  .addEdge("check_query", "run_query")
  .addEdge("run_query", "generate_query");

const agent = builder.compile();
import * as fs from "node:fs/promises";

const drawableGraph = await agent.getGraphAsync();
const image = await drawableGraph.drawMermaidPng();
const imageBuffer = new Uint8Array(await image.arrayBuffer());

await fs.writeFile("graph.png", imageBuffer);
question = "Which genre on average has the longest tracks?"

stream = agent.stream_events(
    {"messages": [{"role": "user", "content": question}]},
    version="v3",
)
for message in stream.messages:
    for token in message.text:
        print(token, end="", flush=True)

final_state = stream.output
const question = "Which genre on average has the longest tracks?";

const stream = await agent.streamEvents(
  { messages: [{ role: "user", content: question }] },
  { version: "v3" },
);

for await (const message of stream.messages) {
  for await (const token of message.text) {
    process.stdout.write(token);
  }
}

const finalState = await stream.output;
================================ Human Message =================================

Which genre on average has the longest tracks?
================================== Ai Message ==================================

Available tables: Album, Artist, Customer, Employee, Genre, Invoice, InvoiceLine, MediaType, Playlist, PlaylistTrack, Track
================================== Ai Message ==================================
Tool Calls:
  sql_db_schema (call_yzje0tj7JK3TEzDx4QnRR3lL)
 Call ID: call_yzje0tj7JK3TEzDx4QnRR3lL
  Args:
    table_names: Genre, Track
================================= Tool Message =================================
Name: sql_db_schema


CREATE TABLE "Genre" (
	"GenreId" INTEGER NOT NULL,
	"Name" NVARCHAR(120),
	PRIMARY KEY ("GenreId")
)

/*
3 rows from Genre table:
GenreId	Name
1	Rock
2	Jazz
3	Metal
*/


CREATE TABLE "Track" (
	"TrackId" INTEGER NOT NULL,
	"Name" NVARCHAR(200) NOT NULL,
	"AlbumId" INTEGER,
	"MediaTypeId" INTEGER NOT NULL,
	"GenreId" INTEGER,
	"Composer" NVARCHAR(220),
	"Milliseconds" INTEGER NOT NULL,
	"Bytes" INTEGER,
	"UnitPrice" NUMERIC(10, 2) NOT NULL,
	PRIMARY KEY ("TrackId"),
	FOREIGN KEY("MediaTypeId") REFERENCES "MediaType" ("MediaTypeId"),
	FOREIGN KEY("GenreId") REFERENCES "Genre" ("GenreId"),
	FOREIGN KEY("AlbumId") REFERENCES "Album" ("AlbumId")
)

/*
3 rows from Track table:
TrackId	Name	AlbumId	MediaTypeId	GenreId	Composer	Milliseconds	Bytes	UnitPrice
1	For Those About To Rock (We Salute You)	1	1	1	Angus Young, Malcolm Young, Brian Johnson	343719	11170334	0.99
2	Balls to the Wall	2	2	1	U. Dirkschneider, W. Hoffmann, H. Frank, P. Baltes, S. Kaufmann, G. Hoffmann	342562	5510424	0.99
3	Fast As a Shark	3	2	1	F. Baltes, S. Kaufman, U. Dirkscneider & W. Hoffman	230619	3990994	0.99
*/
================================== Ai Message ==================================
Tool Calls:
  sql_db_query (call_cb9ApLfZLSq7CWg6jd0im90b)
 Call ID: call_cb9ApLfZLSq7CWg6jd0im90b
  Args:
    query: SELECT Genre.Name, AVG(Track.Milliseconds) AS AvgMilliseconds FROM Track JOIN Genre ON Track.GenreId = Genre.GenreId GROUP BY Genre.GenreId ORDER BY AvgMilliseconds DESC LIMIT 5;
================================== Ai Message ==================================
Tool Calls:
  sql_db_query (call_DMVALfnQ4kJsuF3Yl6jxbeAU)
 Call ID: call_DMVALfnQ4kJsuF3Yl6jxbeAU
  Args:
    query: SELECT Genre.Name, AVG(Track.Milliseconds) AS AvgMilliseconds FROM Track JOIN Genre ON Track.GenreId = Genre.GenreId GROUP BY Genre.GenreId ORDER BY AvgMilliseconds DESC LIMIT 5;
================================= Tool Message =================================
Name: sql_db_query

[('Sci Fi & Fantasy', 2911783.0384615385), ('Science Fiction', 2625549.076923077), ('Drama', 2575283.78125), ('TV Shows', 2145041.0215053763), ('Comedy', 1585263.705882353)]
================================== Ai Message ==================================

The genre with the longest tracks on average is "Sci Fi & Fantasy," with an average track length of approximately 2,911,783 milliseconds. Other genres with relatively long tracks include "Science Fiction," "Drama," "TV Shows," and "Comedy."
参见 LangSmith 跟踪 了解上述运行情况。
参见 LangSmith 跟踪 了解上述运行情况。
6. 实现人工审核
在执行任何可能产生意外行为或低效性的 SQL 查询之前,检查智能体的 SQL 查询是明智的。 这里我们利用 LangGraph 的 人工审核 功能在执行 SQL 查询前暂停运行并等待人工审核。使用 LangGraph 的 持久化层,我们可以无限期地暂停运行(至少只要持久化层存活)。 让我们将sql_db_query 工具封装在一个接收人类输入的节点中。我们可以使用 中断 函数实现这一点。下面,我们允许输入以批准工具调用、编辑其参数或提供用户反馈。
:::python
from langchain.tools import tool
from langgraph.types import interrupt
from langchain_core.runnables import RunnableConfig


@tool(
    run_query_tool.name,
    description=run_query_tool.description,
    args_schema=run_query_tool.args_schema,
)
def run_query_tool_with_interrupt(config: RunnableConfig, **tool_input):
    request = {
        "action": run_query_tool.name,
        "args": tool_input,
        "description": "Please review the tool call",
    }
    response = interrupt([request])
    # approve the tool call
    if response["type"] == "accept":
        tool_response = run_query_tool.invoke(tool_input, config)
    # update tool call args
    elif response["type"] == "edit":
        tool_input = response["args"]["args"]
        tool_response = run_query_tool.invoke(tool_input, config)
    # respond to the LLM with user feedback
    elif response["type"] == "response":
        user_feedback = response["args"]
        tool_response = user_feedback
    else:
        raise ValueError(f"Unsupported interrupt response type: {response['type']}")

    return tool_response


# Redefine the tool node to use the interrupt version
run_query_node = ToolNode([run_query_tool_with_interrupt], name="run_query")
import { RunnableConfig } from "@langchain/core/runnables";
import { interrupt } from "@langchain/langgraph";

const queryToolWithInterrupt = tool(
  async (input, config: RunnableConfig) => {
    const request = {
      action: queryTool.name,
      args: input,
      description: "Please review the tool call",
    };
    const response = interrupt([request]);
    // approve the tool call
    if (response.type === "accept") {
      const toolResponse = await queryTool.invoke(input, config);
      return toolResponse;
    }
    // update tool call args
    else if (response.type === "edit") {
      const editedInput = response.args.args;
      const toolResponse = await queryTool.invoke(editedInput, config);
      return toolResponse;
    }
    // respond to the LLM with user feedback
    else if (response.type === "response") {
      const userFeedback = response.args;
      return userFeedback;
    } else {
      throw new Error(`Unsupported interrupt response type: ${response.type}`);
    }
  },
  {
    name: queryTool.name,
    description: queryTool.description,
    schema: queryTool.schema,
  },
);
from langgraph.checkpoint.memory import InMemorySaver

def should_continue(state: MessagesState) -> Literal[END, "run_query"]:
    messages = state["messages"]
    last_message = messages[-1]
    if not last_message.tool_calls:
        return END
    else:
        return "run_query"

builder = StateGraph(MessagesState)
builder.add_node(list_tables)
builder.add_node(call_get_schema)
builder.add_node(get_schema_node, "get_schema")
builder.add_node(generate_query)
builder.add_node(run_query_node, "run_query")

builder.add_edge(START, "list_tables")
builder.add_edge("list_tables", "call_get_schema")
builder.add_edge("call_get_schema", "get_schema")
builder.add_edge("get_schema", "generate_query")
builder.add_conditional_edges(
    "generate_query",
    should_continue,
)
builder.add_edge("run_query", "generate_query")

checkpointer = InMemorySaver()
agent = builder.compile(checkpointer=checkpointer)
import { Command, MemorySaver } from "@langchain/langgraph";

const shouldContinueWithHuman: ConditionalEdgeRouter<{ InputSchema: typeof MessagesState; Nodes: "run_query" }> = (state) => {
  const messages = state.messages;
  const lastMessage = messages[messages.length - 1];
  if (!AIMessage.isInstance(lastMessage) || !lastMessage.tool_calls?.length) {
    return END;
  } else {
    return "run_query";
  }
};

const builderWithHuman = new StateGraph(MessagesState)
  .addNode("list_tables", listTables)
  .addNode("call_get_schema", callGetSchema)
  .addNode("get_schema", getSchemaNode)
  .addNode("generate_query", generateQuery)
  .addNode("run_query", runQueryNodeWithInterrupt)
  .addEdge(START, "list_tables")
  .addEdge("list_tables", "call_get_schema")
  .addEdge("call_get_schema", "get_schema")
  .addEdge("get_schema", "generate_query")
  .addConditionalEdges("generate_query", shouldContinueWithHuman)
  .addEdge("run_query", "generate_query");

const checkpointer = new MemorySaver();
const agentWithHuman = builderWithHuman.compile({ checkpointer });
question = "Which genre on average has the longest tracks?"

stream = agent.stream_events(
    {"messages": [{"role": "user", "content": question}]},
    config,
    version="v3",
)
for message in stream.messages:
    for token in message.text:
        print(token, end="", flush=True)
if stream.interrupted:
    action = stream.interrupts[0]
    print("INTERRUPTED:")
    for request in action.value:
        print(json.dumps(request, indent=2))
const hitlQuestion = "Which genre on average has the longest tracks?";

const hitlStream = await agentWithHuman.streamEvents(
  { messages: [{ role: "user", content: hitlQuestion }] },
  { ...config, version: "v3" },
);

for await (const message of hitlStream.messages) {
  for await (const token of message.text) {
    process.stdout.write(token);
  }
}

// Check for interrupts
if (hitlStream.interrupted) {
  console.log("\nINTERRUPTED:");
  console.log(JSON.stringify(hitlStream.interrupts[0], null, 2));
}
...

INTERRUPTED:
{
  "action": "sql_db_query",
  "args": {
    "query": "SELECT Genre.Name, AVG(Track.Milliseconds) AS AvgLength FROM Track JOIN Genre ON Track.GenreId = Genre.GenreId GROUP BY Genre.Name ORDER BY AvgLength DESC LIMIT 5;"
  },
  "description": "Please review the tool call"
}
from langgraph.types import Command

stream = agent.stream_events(
    Command(resume={"type": "accept"}),
    # Command(resume={"type": "edit", "args": {"query": "..."}}),
    config,
    version="v3",
)
for message in stream.messages:
    for token in message.text:
        print(token, end="", flush=True)
if stream.interrupted:
    action = stream.interrupts[0]
    print("INTERRUPTED:")
    for request in action.value:
        print(json.dumps(request, indent=2))
const resumeStream = await agentWithHuman.streamEvents(
  new Command({ resume: { type: "accept" } }),
  // new Command({ resume: { type: "edit", args: { query: "..." } } }),
  { ...config, version: "v3" },
);

for await (const message of resumeStream.messages) {
  for await (const token of message.text) {
    process.stdout.write(token);
  }
}
================================== Ai Message ==================================
Tool Calls:
  sql_db_query (call_t4yXkD6shwdTPuelXEmY3sAY)
 Call ID: call_t4yXkD6shwdTPuelXEmY3sAY
  Args:
    query: SELECT Genre.Name, AVG(Track.Milliseconds) AS AvgLength FROM Track JOIN Genre ON Track.GenreId = Genre.GenreId GROUP BY Genre.Name ORDER BY AvgLength DESC LIMIT 5;
================================= Tool Message =================================
Name: sql_db_query

[('Sci Fi & Fantasy', 2911783.0384615385), ('Science Fiction', 2625549.076923077), ('Drama', 2575283.78125), ('TV Shows', 2145041.0215053763), ('Comedy', 1585263.705882353)]
================================== Ai Message ==================================

The genre with the longest average track length is "Sci Fi & Fantasy" with an average length of about 2,911,783 milliseconds. Other genres with long average track lengths include "Science Fiction," "Drama," "TV Shows," and "Comedy."
下一步
查阅 评估图 指南,了解如何使用 LangSmith 评估 LangGraph 应用,包括像这样的 SQL 智能体。官方原文:src/oss/langgraph/sql-agent.mdx · 非官方翻译,译文由 AI 生成,以英文原文为准。